When an integration fails, answering “what did our application receive?” can mean searching through logs, database queries, and provider dashboards. A webhook inbox in PHP provides an operational record of the events received and their journey through the system. Its purpose is to reconstruct what arrived, what was attempted, and what needs attention—not to replace every processing component.
Designing one well requires separating receipt, validation, and execution; recording useful metadata without accumulating sensitive data; and defining how to repeat an operation without duplicating business effects. The tool must make the limits of what it knows clear: recording that an event was accepted does not prove that the subsequent effect was completed.
When You Need an Inbox
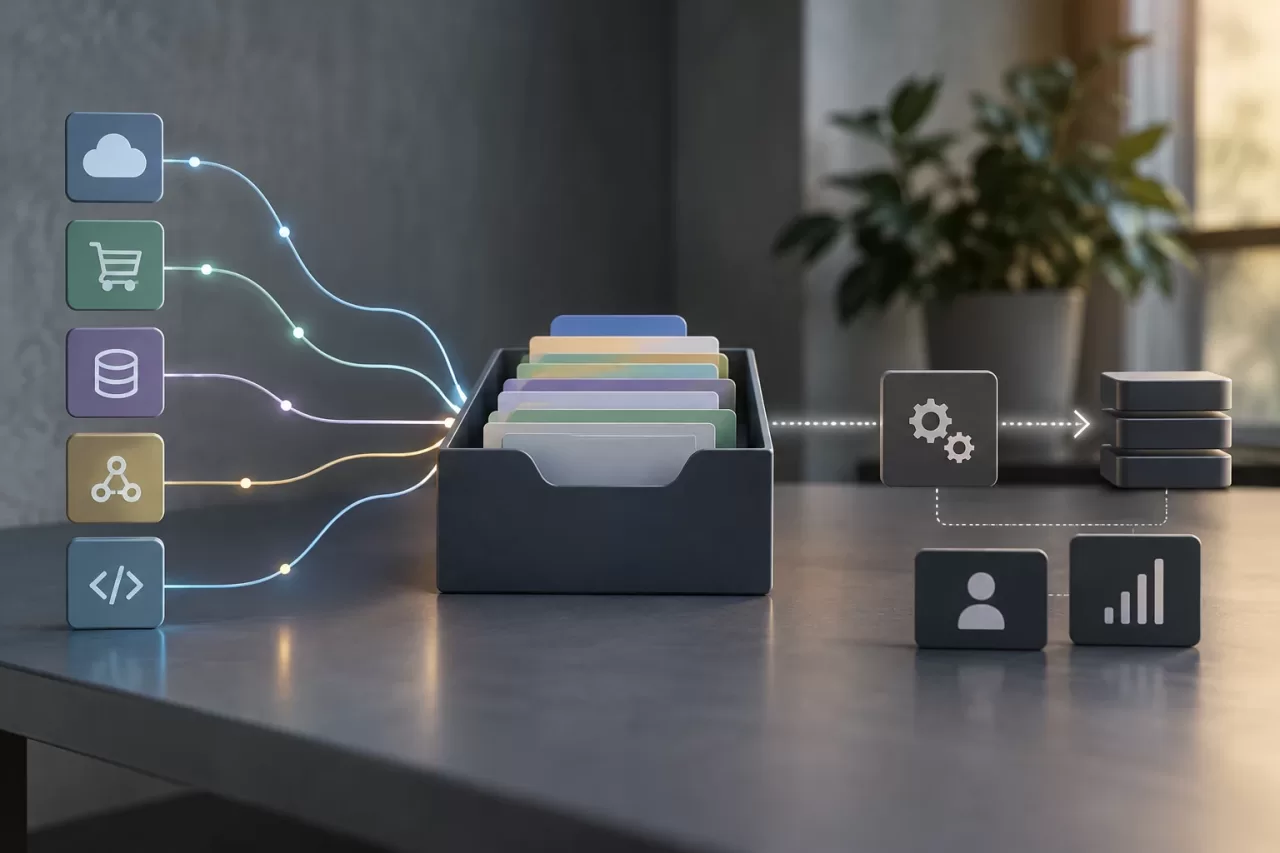
An inbox can be useful if a system receives events from multiple providers, if intermittent failures are difficult to reproduce, or if support and engineering need to consult the history without direct access to production. It also helps when a successful HTTP response only confirms receipt while processing continues asynchronously.
You do not always need to build a custom interface. For a simple, low-volume integration whose errors are already visible in existing tools, structured logs and alerts may be enough. Before adding an inbox, check what information the provider offers, how long its history is retained, and what observability tools the team has. Avoid creating a second source of truth without a clear operational need.
An inbox is not a job queue or a change-audit system either. The queue manages pending work, concurrency, availability, and execution attempts. The inbox describes event receipt and operational status. The audit log records who changed what and when in the domain. They can be linked by identifiers, but each answers different questions.
Separate Receipt, Validation, and Processing
An endpoint should verify transport and authenticity requirements before accepting the event: for example, validate the signature according to the provider’s mechanism and check that the body has an acceptable format. It can then record receipt and dispatch the work to a queue. A successful response to the sender should have a precise meaning, such as “received and persisted,” not “the entire business process is complete.”
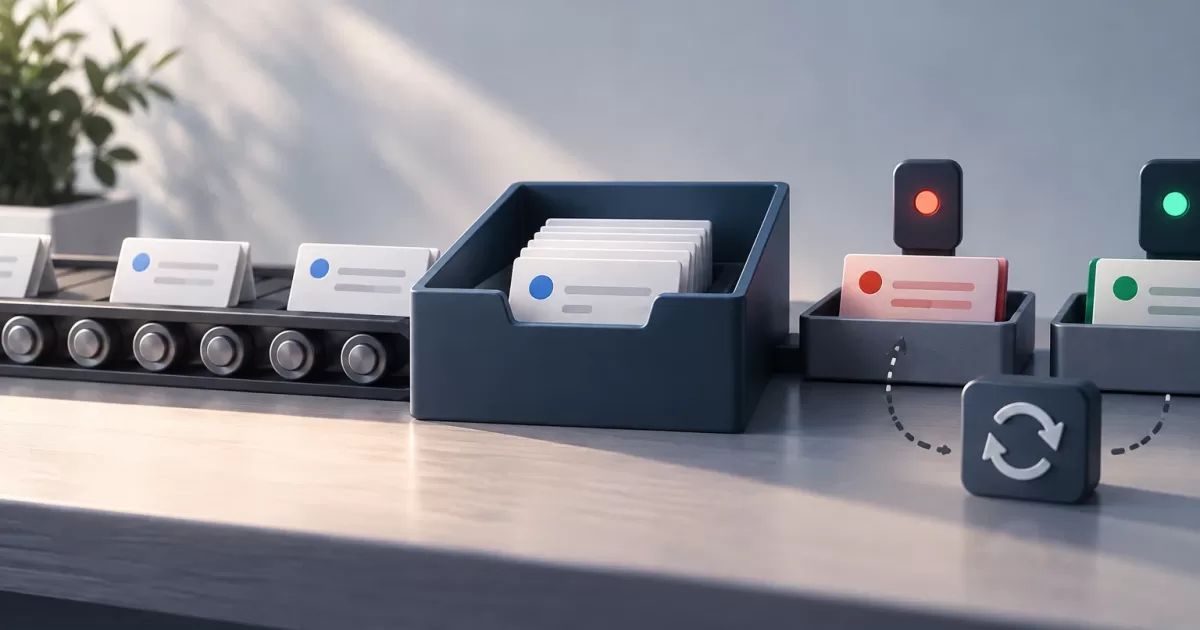
Define explicit states and their transitions. One possible set is received, rejected, queued, processing, processed, and failed. Adapt it to the actual flow: do not use the same state for an invalid event and one that failed because of a temporary dependency. Record when the state changed and, where appropriate, a safe error category for diagnosis. Avoid ambiguous states such as “complete” if only one stage has finished.
If the record is saved and a job is published to a queue, consider the failure window between those two operations. The transactional outbox pattern can help write the event and the intent to publish it in a single transaction, then dispatch that intent. It does not eliminate every failure: the consumer still needs to tolerate duplicate deliveries.
What to Record to Investigate an Event’s Journey
Design a record that makes it possible to find an event and connect its steps. Depending on the provider and the business, include:
- An internal record identifier and the sender’s event identifier, if available.
- The provider, event type, and a non-sensitive reference to the receiving account or integration.
- Receipt, validation, enqueue, and last-update timestamps, using a consistent time convention.
- Current status, number of attempts, and a summary of the result of each execution.
- Correlation or trace identifiers, as well as references to the job and related application records.
- An operationally useful failure category, such as validation error, unavailable dependency, or business conflict.
Preserve the correlation identifier from the endpoint through to the job and the services it calls. This lets someone start with the event and follow execution in logs or distributed traces. Do not copy large blocks of logs into the inbox record: store references and consult the observability system for time-specific details.
Minimize Sensitive Data by Design
Always storing the full payload may seem practical, but it can retain personal data, secrets, or commercial information unnecessarily. Decide field by field what is needed to identify, validate, or repair a failure. Often, the event type, opaque identifiers, and an approved summary are enough. Redact tokens, credentials, and sensitive fields before recording errors.
If the full payload is essential for a retry or investigation, define the reason, authorized access, encryption, retention period, and deletion procedure. Consider storing the content in separate, restricted storage, with a reference from the inbox. Do not assume that hiding fields in the interface protects them in the database, backups, or logs.
An Interface for Decisions, Not Just Inspection
The operational view should allow filtering by integration, type, status, time range, and external or internal identifier. In the detail view, show the timeline, attempts, summarized error, correlation references, and available actions. Make it clear when the data was received and when it was processed; these are different times.
Provide an actionable next step: correct the configuration, wait for a dependency, escalate to the responsible team, or request reprocessing. If the cause points to the provider, the interface should not present a local retry as a guaranteed solution. Metrics and alerts matter too: monitor the age of pending events, failures by type, and events that exceed the defined attempt threshold.
Safe Retries and Idempotency
A retry button should not directly execute an irreversible operation without safeguards. Before allowing it, check that the event is eligible, that its status permits the action, and that no execution is already in progress. Record who requested the retry, when, why, and which execution was created. Permissions should distinguish between viewing and actions that could affect the business.
Idempotency protects against duplicate deliveries and retries: processing the same event more than once should not create two payments, orders, or notifications. Use a stable provider key when it is reliable, together with unique constraints or idempotent mechanisms at the business boundary. Deduplication in the inbox alone does not guarantee that an external call will not be repeated if the process fails after making it.
Define attempt limits, delays, and conditions for stopping retries. Some errors require data or configuration to be corrected before trying again; others are transient. For operations with external effects, establish how to reconcile an uncertain result—for example, when the connection is interrupted after sending a request but before receiving confirmation. If the outcome cannot be determined, escalation may be safer than retrying blindly.
Retention, Permissions, and Action Traceability
Set a retention period that matches support needs and applicable obligations. Delete or anonymize expired records, and verify that the policy also covers separately stored payloads and backups according to their lifecycle. Restrict access by role: being able to view an event does not imply permission to see its sensitive content or reprocess it.
Record administrative actions as audit events separate from the webhook status: actor, action, date, reason, and result. This distinguishes what the provider sent from what someone did through the tool. Protect these records against unauthorized modification and avoid storing secrets in reasons or error messages.
Checklist for an Existing Integration
- Is the meaning of a successful endpoint response defined, and is it clear when persistence is confirmed?
- Do the statuses represent distinct stages, and is there a path for invalid and failed events?
- Can each event be correlated with jobs and logs without duplicating unnecessary information?
- Have sensitive data been identified and minimized, with access and retention defined?
- Do retries have permissions, limits, idempotency, and a way to handle uncertain outcomes?
- Are there alerts for backlogs, persistent failures, and events that require intervention?
A useful inbox reduces the time it takes to understand a failure because it preserves context and makes the event’s journey visible. Its quality does not depend on accumulating fields, but on every piece of data having a purpose, every status meaning something, and every operational action being safe and traceable.