A business process can complete part of its work and fail before finishing. For example, a PHP application creates an account in its database but cannot provision it in an external service. At that point, simply repeating the workflow may duplicate effects; treating it as failed may leave systems inconsistent. Compensating actions in distributed PHP processes let you define how to respond to these partial outcomes without assuming that multiple systems participate in a single atomic transaction.
The important decision is not just how to undo what happened. Some effects cannot be reversed exactly, and a compensating action can fail too. The design must make the operation’s actual state visible, allow it to be recovered, and indicate when human intervention is needed.
Local transactions, retries, and compensating actions solve different problems
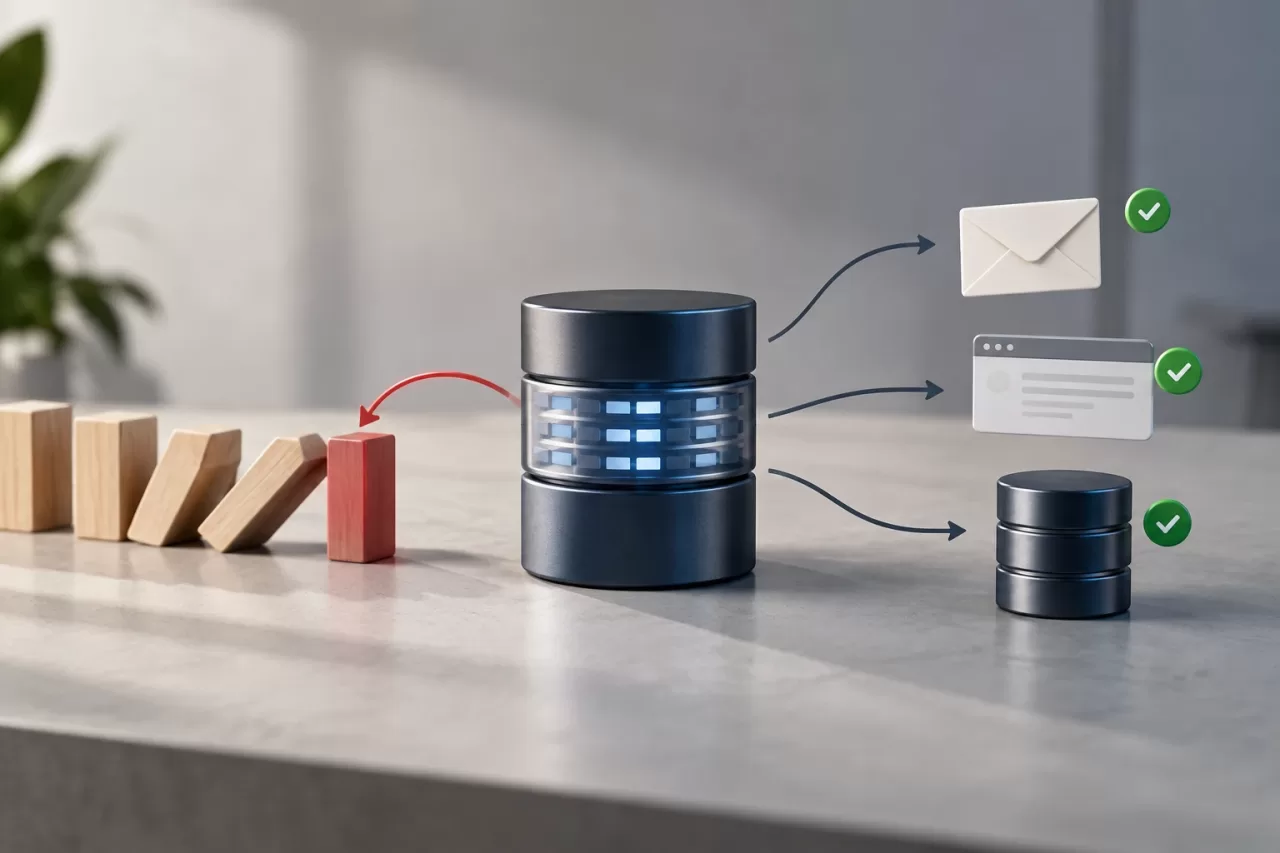
A database transaction protects changes within that database’s boundaries. If the process saves several rows and an operation fails before COMMIT, it can run ROLLBACK to discard those changes. But that rollback does not retract a sent email, automatically cancel a request already accepted by an API, or reverse changes committed in another database.
A retry runs an action again after it may have failed because of a temporary problem, such as a timeout or an outage. It is appropriate only when the consequences of repeating the action are known. The request may have reached the external system even if the response was lost; without an idempotency key or a status check, retrying could create a duplicate.
A compensating action performs a business action that counteracts a completed step—for example, deactivating access that was just created. It is not a technical rollback and does not guarantee that the exact previous state will be restored. Reconciliation, by contrast, compares what is recorded locally with the state of the systems involved and helps detect and resolve discrepancies. It may be necessary even when retries and compensating actions are in place.
Model each operation as a sequence of observable steps
Before writing exception handlers, describe the workflow as independent steps. For each one, specify which system it modifies, what outcome counts as success, how the operation is identified, whether it is safe to repeat, and what alternative exists if it cannot be completed. Also define which effects must remain consistent; that business rule is the invariant that will guide recovery.
Persist a record of the operation and its steps in the application. A simple model might include a stable operation ID, the overall status, the step name, the outcome, the number of attempts, timestamps, and the latest relevant error. States such as pending, in progress, completed, failed, compensating, and requires review help distinguish what is known from what has not yet been confirmed.
Save the local change and the work record atomically when they need to remain linked. A work queue can process the external call afterward; the outbox pattern is one option for preventing the database change from being committed while losing the notification that should initiate the next step. It does not eliminate network failures: the consumer still needs to tolerate duplicate messages and uncertain outcomes.
Avoid keeping a database transaction open during a network call. External calls have latency and can hang, while a long-running transaction holds resources and does not make the two systems atomic. Commit local work according to an explicit sequence and record what is needed to continue or compensate.
Design explicit, bounded, and idempotent compensating actions
For each step that produces an effect, decide whether a compensating action exists and when it should run. The compensating action does not have to be the literal inverse. If an account has already received a notification, you cannot erase the fact that the message was read; it may be appropriate to record a correction or notify the recipient of the cancellation. If an action is irreversible or has legal or financial consequences, the right response may be to stop the workflow and escalate it.
- Idempotency: Running the same compensating action twice must not create additional effects. Use a stable operation ID or an idempotency key when the system supports it, and record the outcome.
- Order: Define which steps are compensated and in what sequence. The usual approach is to try to reverse them in the opposite order from execution, but dependencies and business rules may require a different order.
- Limits: Specify which errors allow retries, how many attempts to make, and when to stop. Apply delays between attempts and avoid indefinite retries.
- Uncertainty: If an API request times out, check its status or use an idempotency key before repeating a creation or running a potentially incorrect compensating action.
Compensation logic should be an identifiable business operation, not a generic block that deletes data when it catches any exception. Preserve the history needed to explain what happened and verify that the response complies with the product’s rules.
Hypothetical example: creating an account in two systems
Suppose a workflow creates a local account and asks an external provider to activate a workspace. The application assigns an operation ID and records the account creation as pending. In a local transaction, it saves the account and a job to request provisioning. A PHP worker processes the job and records the external ID and the request outcome.
If the provider confirms activation, the workflow marks the operation as completed. If it returns a known temporary error, the job can be retried within defined limits and with the same idempotency key. If the response is uncertain, the application first tries to find out whether the workspace exists. If the provider confirms that the workspace was created, but a later local requirement prevents the account setup operation from being completed, the system can request the workspace’s deactivation as a compensating action and save the outcome.
If deactivation fails, the account creation must not be declared rolled back. The operation remains in a visible state such as recovery pending or requires review, with the local and external IDs, the attempts, and the error. The operations team needs a procedure to check with the provider, decide on the permitted action, and record the outcome. This example is hypothetical: the specific actions depend on the API’s capabilities and the business rules.
When compensation also fails: visibility and review
A distributed workflow cannot promise that every action will be automatically undone. Design an explicit outcome for exhausted retries, an ambiguous external response, or a failed compensating action. Preserve the state without hiding the inconsistency, and avoid presenting the operation to the user as completed if it is not.
Give support or operations a view that shows the status of each step, the latest error, correlation IDs, and permitted actions. Human review must have access controls and leave an audit trail of the decision. Expose metrics and alerts to detect stuck operations, failed compensating actions, and discrepancies that exceed the acceptable operational timeframe. A periodic reconciliation task can compare local records with the external system and open cases to resolve discrepancies.
Test partial failures and decide whether compensation is needed
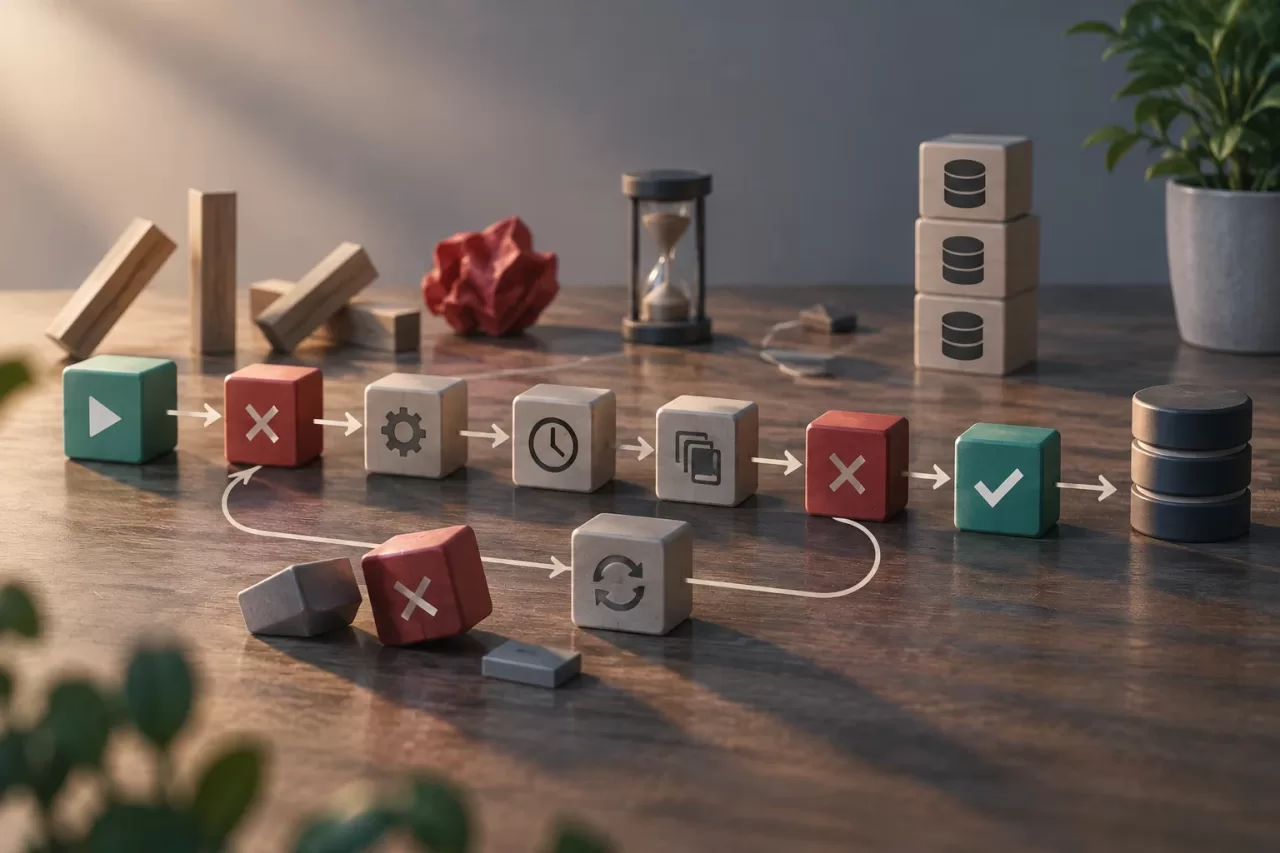
Tests should cover more than the successful path. Simulate errors before and after each effect, delayed responses, timeouts with unknown outcomes, duplicate messages, interrupted processes, and failures during compensation. Verify the persisted state after restarting the worker and confirm that retries do not duplicate accounts or other operations.
- Are the operation ID and the outcome of each step preserved?
- Does a repeated message produce the same outcome without duplicate effects?
- Is the external status checked when the response to a request is uncertain?
- Does compensation run in the intended order, and is it safe to repeat?
- Does a compensation failure leave the operation visible and route it to the review process?
- Can the local state be reconciled with the external system afterward?
- Do the tests check business invariants, not just response codes?
If the workflow affects a single system and a local transaction protects all its changes, that transaction and straightforward recovery may be enough. If there are repeatable external effects with known guarantees, idempotent retries and reconciliation may be sufficient. When a completed step must be counteracted to preserve a business rule, define a compensating action. The added complexity is worthwhile when the cost of leaving partial states undetected outweighs the cost of maintaining the record, tests, and operational procedure.