A deletion request is not resolved by running a DELETE against the users table. In an application with multiple modules, information may appear in related records, files, search indexes, queues, exports, or external services. Deleting only the visible account can leave accessible copies; deleting blindly can affect data that must be retained for other processes to keep working.
Verifiable data deletion in PHP is designed as a process with explicit scope, owners, states, retries, and checks. The operational goal is not to promise that every copy disappears immediately; it is to identify which destinations were processed, what result each one returned, and what outstanding limitations remain.
Define the scope before execution
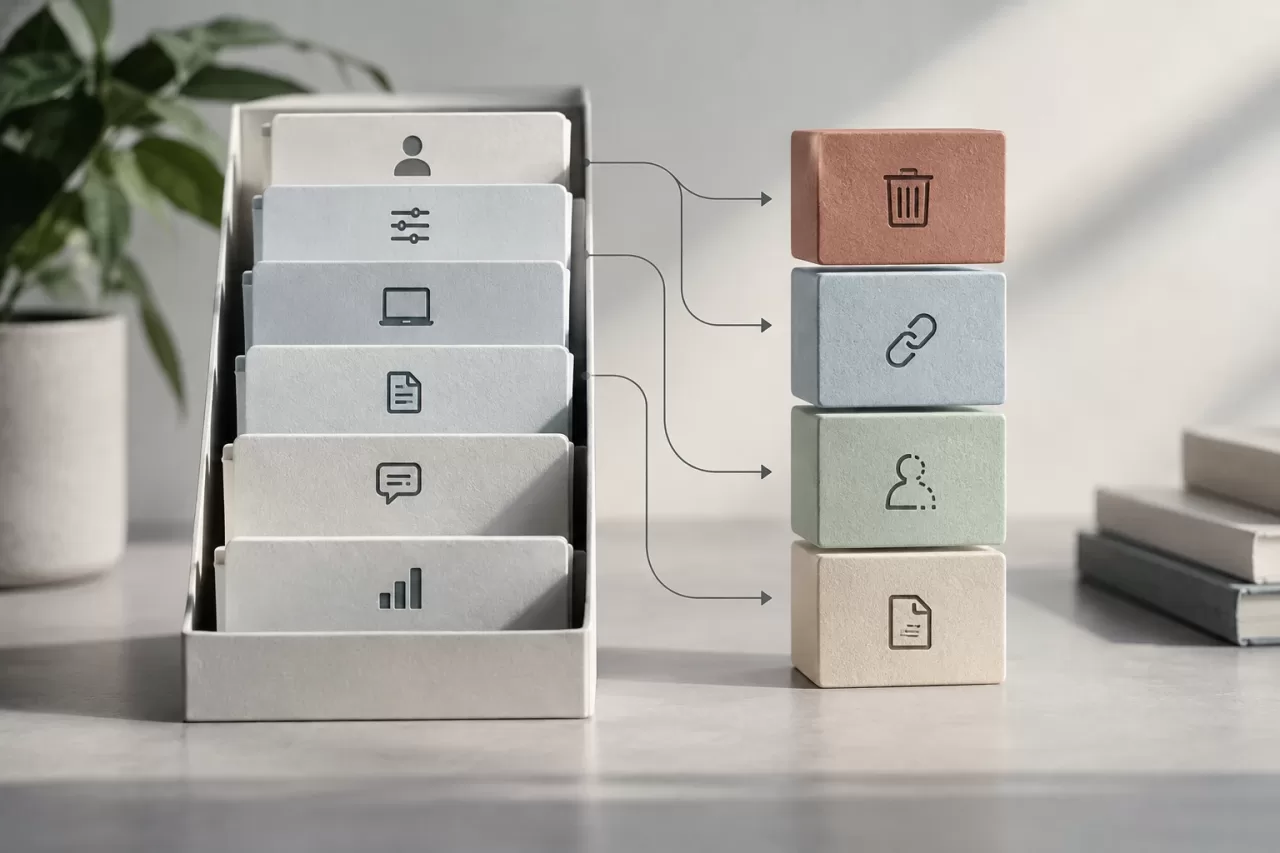
Translate the request into an inventory of data categories and systems. For example, an account may have a profile, preferences, sessions, documents, comments, and activity events. It may also have references in invoices or other shared records. For each category, decide whether it should be deleted, unlinked, anonymized, or retained under an applicable internal policy. Do not treat these options as equivalent: anonymization requires that the person can no longer be identified in the intended context, while unlinking does not necessarily delete the original data.
Also define what “complete” means for each destination. Removing a row from the primary database does not prove that the search index has been updated or that a file has been deleted. Separate destinations under direct control—database, object storage, cache—from those that depend on a provider or a retention window, such as certain backups. The final state should reflect these differences, not hide them under a single success label.
Inventory copies and assign owners
The inventory should follow actual data flows, not just the database schema. Review where data is created, exported, or transformed: job queues, search indexes, analytics systems, temporary files, application logs, and connected tools. Ask each team which identifier can locate the records and what operation its system supports.
Assign a technical owner for each destination and document the mechanism, expected response, retries, and limitations. If a system cannot search by a stable identifier, that shortcoming makes verification harder and should be treated as design debt. Avoid storing an additional copy of personal data in the request record itself: an internal case ID, the reference needed to perform the operation, and minimized results are usually sufficient.
Model states and results by system
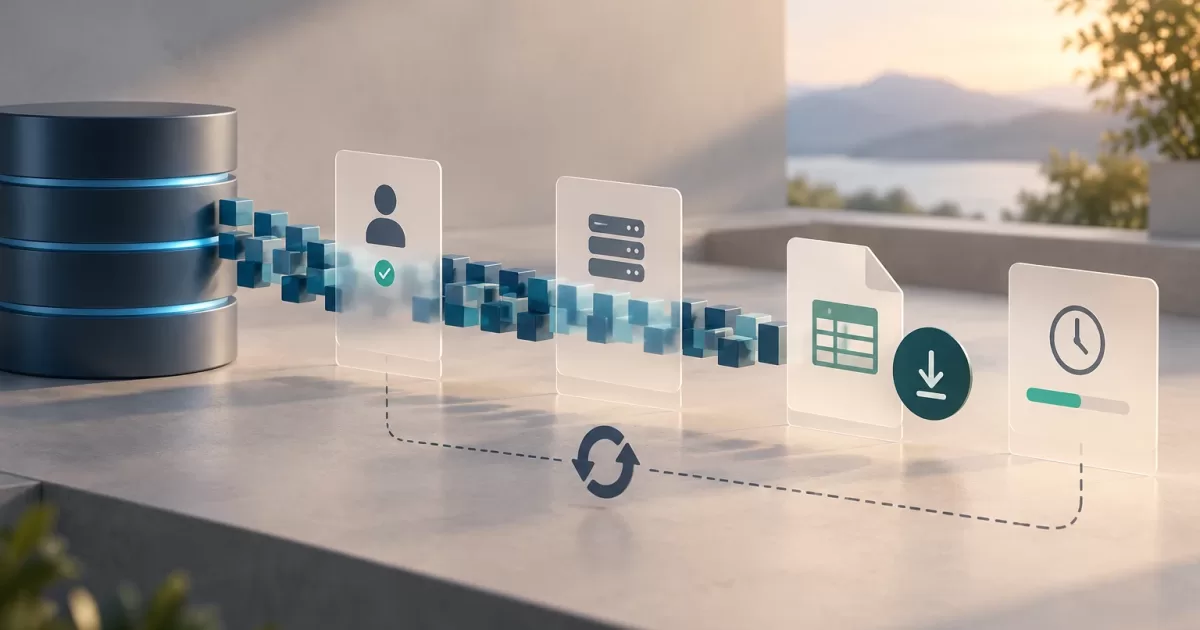
A robust process has explicit states, for example: received, validated, in_progress, partially_completed, verification_pending, completed, and failed. Agree on the transitions and who can initiate them. A request should not be marked complete while any required destination lacks a verifiable result.
Record the result for each system separately: pending, deleted, not found, retryable, requires review, or subject to a documented limitation. “Not found” may be a valid result, but only if the query used the correct key and covered the intended scope. Distinguish a transient failure—for example, an unavailable service—from a permanent rejection that requires intervention.
In PHP, separate orchestration from the work specific to each destination. An application service can load the case, check permissions, and dispatch tasks; independent adapters implement operations for the database, storage, or APIs. That way, a provider change does not force you to mix business logic with transport details. Also protect case creation and lookup with access controls, and record who initiated administrative actions.
Order deletion while respecting dependencies
Before deleting, determine which relationships depend on the account and which are shared. Foreign keys and cascade delete rules help maintain integrity, but a cascade can delete more than intended if the model mixes owned and shared data. Review the impact of each relationship and prefer explicit operations when the scope is not obvious.
A common sequence is to stop new writes associated with the subject, invalidate sessions or credentials, remove internal dependencies, delete or transform the subject’s own records, and then propagate the operation to indexes and external services. The exact order depends on the architecture. If you delete first the key used to locate data in other systems, the task may lose the information it needs to continue. Keep that working reference protected and only for as long as necessary, without turning the operational record into a parallel data store.
Make the workflow idempotent and resumable
Distributed jobs can fail after completing an operation but before reporting it. For this reason, each step must be repeatable without causing unintended effects. An idempotent deletion can accept that a record no longer exists and return a controlled result, rather than always treating it as an error.
Save progress by destination and use an idempotency key or stable case ID when the remote system supports it. Process each destination in an appropriate transaction or unit of work, without keeping a database transaction open while waiting for an API. If a failure occurs, retry with limits and a backoff strategy; exhausted errors should go to a review queue, not disappear into a log.
Resumption should continue from the incomplete steps. Do not restart the entire workflow if that could repeat unsafe actions or overwrite previous results. In particular, distinguish between “request sent” and “deletion confirmed”: a successful HTTP response may confirm receipt, not necessarily completion of the remote work. Define the meaning of each acknowledgment with the provider.
Verify without retaining what is deleted
Verification should match the destination and type of operation. In the database, a query using the intended keys can confirm that no rows remain within scope. In storage, you can check that the object is absent or inspect the response from the deletion mechanism. In an index, you need to query the document using an appropriate key and account for propagation time. A worker’s success message does not replace these checks.
Record minimal evidence: case ID, destination, operation, timestamp, status, number of affected items when safe, and a technical reference for the result. Avoid copying deleted content, credentials, tokens, or unnecessary personal identifiers into logs and metrics. Protect the audit log, restrict access to it, and define its internal retention period. The evidence should make it possible to explain the process without recreating the information that was meant to be removed.
Manage limitations and test the workflow
Backups require explicit handling. They may not support immediate selective deletion; document the intended retention cycle and how you prevent a restore from reintroducing data that has already been deleted. For example, the recovery procedure can reapply pending or completed requests before enabling the restored system. Do not claim that a backup has been deleted if the available mechanism only allows it to expire according to its retention period.
For external systems, specify who can initiate the operation, what confirmation the provider offers, and when an uncertain result should be escalated. An operational limitation is not equivalent to successful verification: based on the available evidence, it must be shown as pending, restricted, or resolved.
Before operating the workflow, test it in non-production environments with synthetic data: duplicate requests, shared relationships, missing files, timeouts, ambiguous responses, and failures after a step has completed. Check that retries do not duplicate effects, permissions block unauthorized access, and reports do not expose data. In production, monitor failure volume, the age of pending cases, and destinations without confirmation, without including personal information in alerts.
Checklist: scope and exceptions defined; destinations and owners inventoried; states and transitions documented; dependencies reviewed; steps idempotent and resumable; verification specific to each system; evidence minimized and protected; backup and provider limitations communicated; failure scenarios tested; review and escalation procedure available. With these controls, the team can respond with traceability and identify exactly where a deletion stopped, rather than confusing an initiated action with a confirmed result.