A retention and deletion policy cannot be implemented with a single DELETE statement. In a PHP application, the same information may appear in multiple tables, files, caches, logs, and external services. If the process only deletes the primary row, it may leave active copies behind; if it deletes data without checking dependencies, it may disrupt operations or remove data that should have been retained.
The practical goal is to turn each rule into a workflow that identifies the affected data, applies the appropriate action, handles exceptions, and leaves verifiable evidence. The policy should be agreed upon by the teams responsible for product, technology, and data, and checked against the obligations that apply to the business. Do not assume that legal retention periods are universal: they depend on the context and must be validated before being automated.
Start with data categories and retention rules
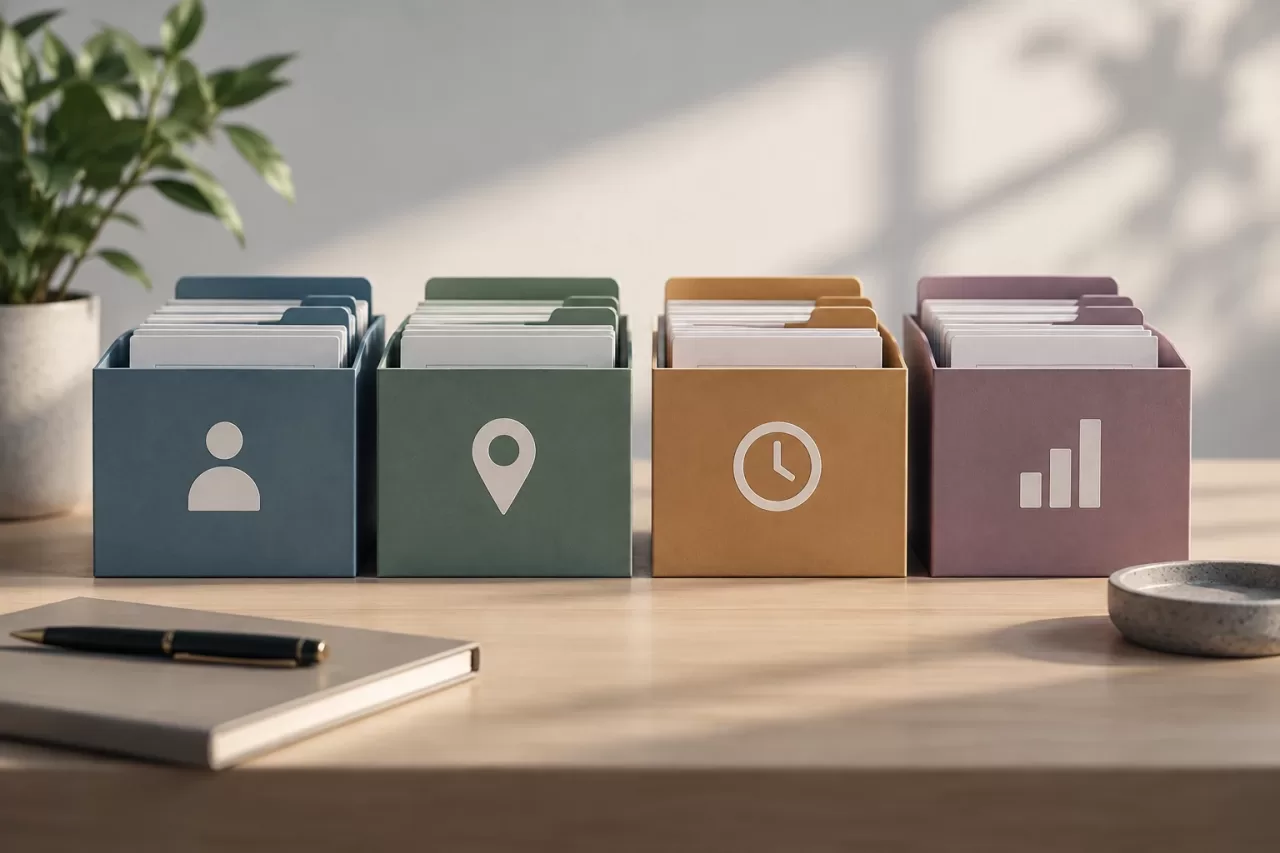
Before designing deletion, classify information according to its purpose and use. A profile, an address needed for a pending transaction, an activity history, and an accounting record may be subject to different rules, even if they are associated with the same account.
For each category, document at least:
- Purpose and owner: why the data is stored and which team decides how long it is retained.
- Triggering event: for example, account closure, the end of a relationship, or a validated request.
- Period and condition: when the action is reviewed or performed, including any justified suspensions.
- Action: delete, anonymize, retain with restricted access, or refer for manual review.
- Dependencies: systems and processes that must be completed before the case can be considered resolved.
“Retain” does not mean keeping data indefinitely for convenience. There must be a reason, a scope, and a review date or condition. If some information must be kept for an operational need, separate it from the rest and limit who can access it.
Inventory copies, references, and connected systems
The inventory should follow the data’s actual path, not just the database schema. Examine related tables, JSON fields, uploaded files, exports, search indexes, caches, queues, application logs, and integrated systems. Also include workflows that create copies, such as reports, support tools, analytics, or import processes.
For each location, note which identifier can be used to find the data, who is responsible for it, how it is deleted or updated, and what happens if the system is unavailable. Review relationships through foreign keys and application logic: a database relationship may prevent cascading deletion, while a cascading deletion may remove more than intended.
Treat backups as a separate case. It may not be possible to delete an individual item without restoring the entire backup. Define how access to backups is restricted, how long they are retained, and what procedure prevents deleted data from returning to active systems after a restore. Document the decision and validate it with the people responsible for infrastructure and compliance.
Decide when to delete, anonymize, or retain
Physical deletion removes data from an active system, but it is not always the right choice for every record. Anonymization may be appropriate when statistical information must be retained and it is possible to effectively remove the ability to link it to an individual. Replacing a name with a stable identifier is not enough if another table can be used to reconstruct the relationship.
Restricted retention may be suitable for data that is still needed for an operation or a validated obligation. Keep these items separate, with specific permissions and a review rule. If you cannot safely determine which action applies—for example, because of a dispute, an unknown dependency, or an identity inconsistency—send the case to a review queue instead of improvising.
You also need to review functional consequences: what happens to orders, subscriptions, tickets, API keys, or shared documents when an account is removed. Behavior must be explicit and consistent across the interface, PHP logic, and connected services.
Implement an idempotent, observable workflow
A deletion process is often run in the background, through a queue or a scheduled task. Model the case with explicit states, such as requested, validated, in progress, pending external systems, completed, or requires review. Define allowed transitions and who can retry or close an exception.
Idempotency is essential: repeating a step must not duplicate effects or cause damage. Before deleting a file, check that it exists; when processing a request, verify its current state; when calling an external service, use idempotency mechanisms if available. If you cannot guarantee this, record the response and design a reconciliation process before blindly retrying.
A conceptual PHP example could separate orchestration from actions for each system:
foreach ($steps as $step) {
    if ($step->isComplete($requestId)) {
        continue;
    }

    $step->execute($subjectReference);
    $step->markComplete($requestId);
}
The example does not solve distributed transactions: a database and an external provider do not necessarily share a transaction. Store progress reliably, handle errors at each step, and allow the work to resume. If an operation fails partway through, the state must indicate what remains; it must not be presented as complete.
Record execution without creating another copy of personal data
Traceability makes it possible to answer who or what process took action, when, on which request, and with what result. Record internal operation identifiers, states, steps, and error codes useful for diagnosis. Avoid copying names, email addresses, documents, file contents, or complete API payloads into logs.
A pseudonymous user identifier may still be sensitive if it can be used to reidentify someone. Restrict access to the logs, limit their retention, and separate operational information from identity where possible. Error messages should help identify the affected system without exposing personal data in monitoring tools.
Verify the outcome and prepare for exceptions
Tests should cover both the normal case and partial failures. Use test data and verify the locations identified in the inventory, not just the primary table. Include scenarios such as a relationship that prevents deletion, a missing file, an unavailable external provider, a retry, and an exception requiring review.
A useful operational checklist asks: Was each known copy located? Was the intended action applied to each category? Are any steps still pending? Did external systems confirm the outcome? Do the logs contain only the information needed? Does a retry preserve the safety of the process? Add periodic checks to detect new tables, integrations, or data paths that may have been left out of the inventory.
Hypothetical example: closing an account
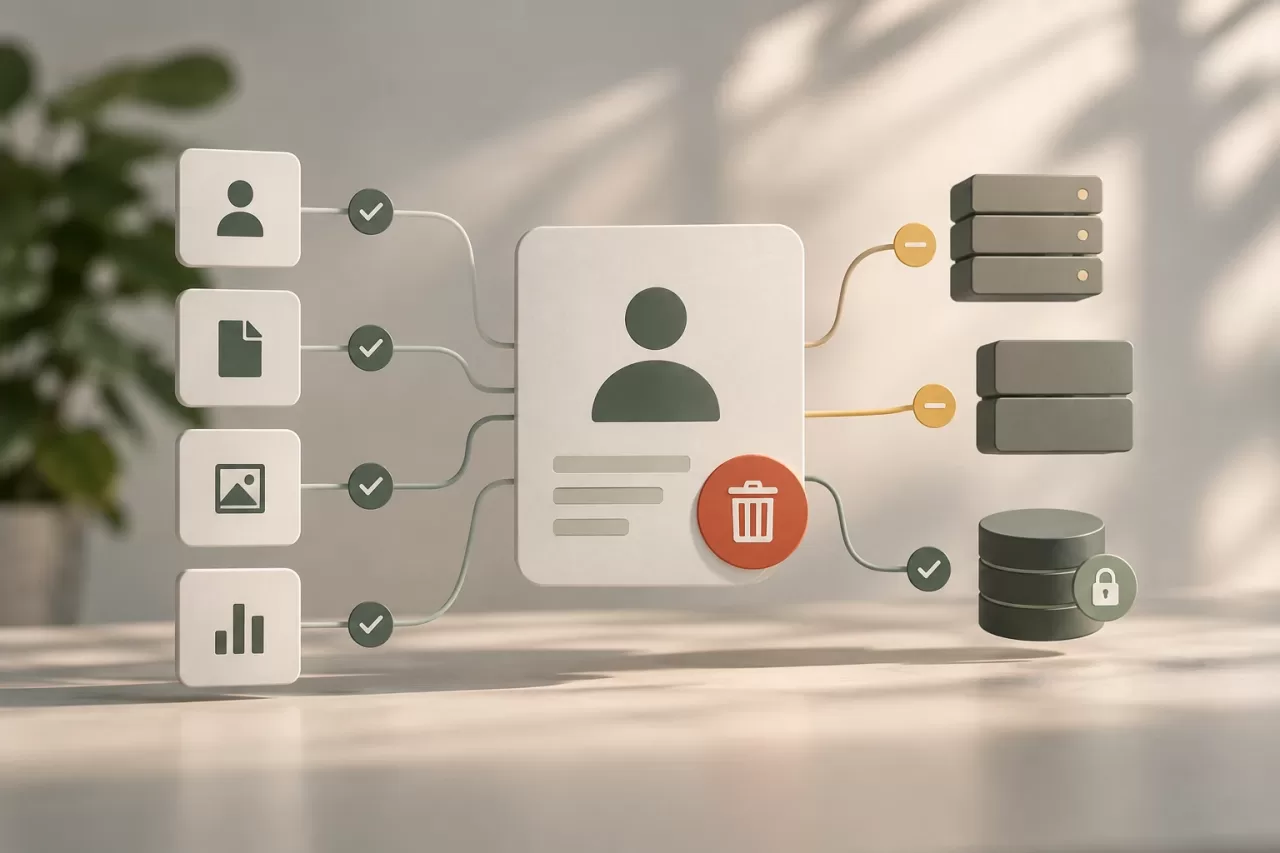
Suppose someone requests to close their account in a PHP application. The workflow validates the request and checks the rules defined for the profile, files, activity, and information associated with pending transactions. Eligible profile data and files are deleted; certain records are retained with restricted access if there is an approved reason; data intended for analytics is kept only if it has been effectively anonymized.
The application records each step without including the email address or file contents. If an external service does not respond, the case remains pending, and a later process retries or requests intervention according to policy. The case is marked complete only when all required actions have been confirmed or a formal exception has been documented and approved.
Before implementation, resolve any outstanding decisions: which systems contain the data, who authorizes exceptions, what “complete” means for each destination, how backups are handled, and who reviews failures. This definition turns an intention to delete into a maintainable, verifiable, and secure process.