A migration can modify millions of records, feed active processes, and produce effects outside the database. If a transformation fails midway, restoring a full backup is not always safe or acceptable: new data may have been written since the backup, or the system may not be able to remain offline for as long as restoration requires.
That is why a rollback plan for data migrations should be more than a command to undo changes. It should establish how to identify the affected state, which operations can be undone, which require compensation, and when it is better to repair or resume. The decision must be prepared before running the migration, using criteria the team can verify under pressure.
Why restoring a backup is not always a viable rollback
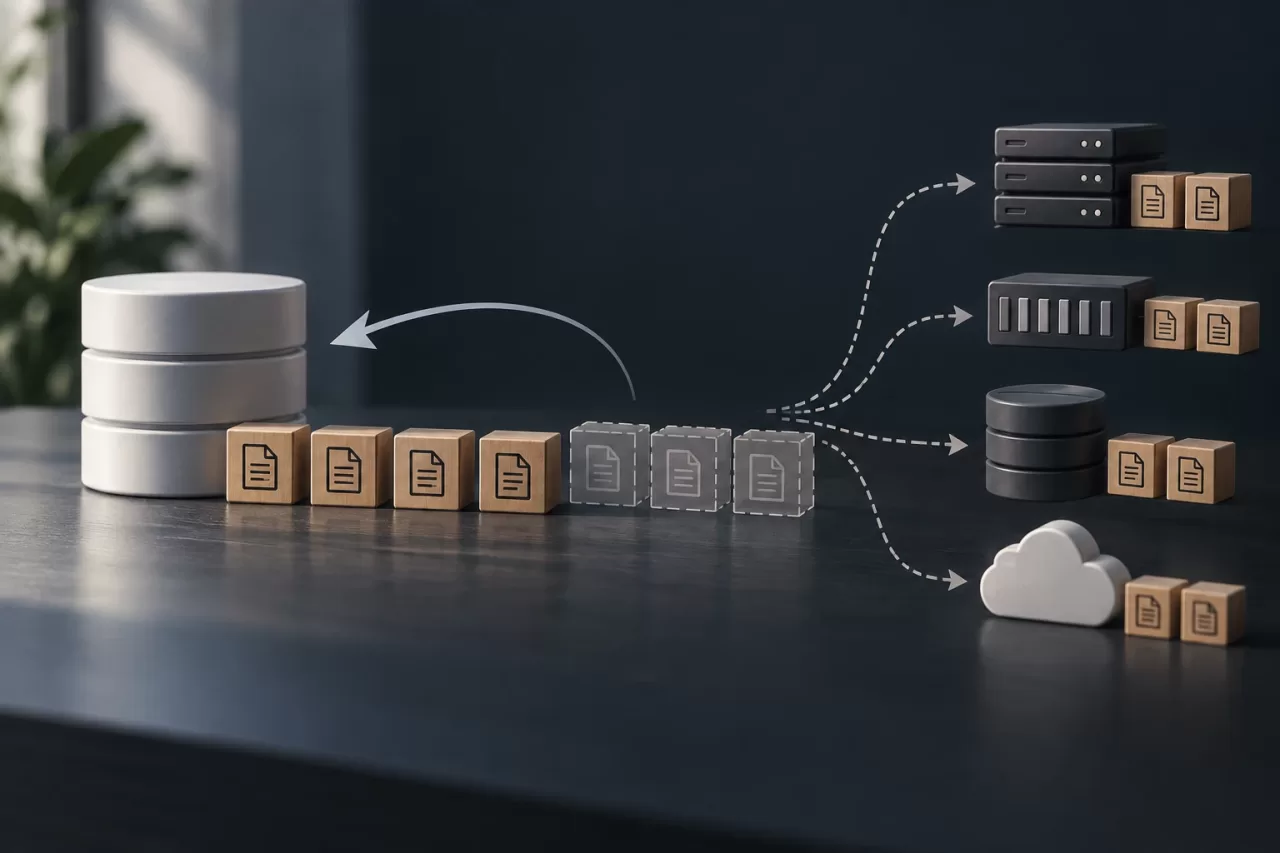
A backup can recover data from certain incidents, but restoring it may remove legitimate changes made after it was created. It can also cause downtime, require indexes to be rebuilt, or lose writes that reached other systems. If replication, queues, exports, or integrations are involved, recovering a database does not automatically undo those effects.
It is useful to distinguish three actions. Restore recovers a backup or a point in time; roll back attempts to undo the migration’s changes; compensate applies new operations to correct their effects. These are not equivalent: compensation may leave a different history from the original, even if it restores the business rules.
The choice depends on the scope of the failure, subsequent writes, and recovery objectives. Before starting, determine what data loss is tolerable, how long the interruption can last, and who authorizes recovery. If those limits are not defined, the team has no operational criteria for making a decision.
Classify each transformation by its recoverability
Describe each migration step and classify it according to its planned recovery method:
- Reversible: a reliable inverse operation exists. For example, the original value is preserved before normalizing a field and can be restored without overwriting subsequent changes.
- Compensable: the exact previous state cannot be reconstructed, but a new operation can correct the effect according to a business rule. Compensation should be explicit, auditable, and idempotent where possible.
- Irreversible: information is discarded or an effect is produced that cannot be reliably undone. This requires an explicit decision about risk acceptance, source-data retention, and additional validation.
Do not assign a label based only on the type of SQL statement. A bulk update may be reversible if the previous value is saved and concurrency is controlled; it may not be reversible if other processes modify the same rows during execution. Also consider side effects such as notifications, API calls, charges, or queue messages. It is often preferable to separate these actions from the data transformation.
Establish the initial state and invariants
Before running the migration, record its scope: included entities, filters, application version, and applied rules. Define a baseline using relevant counts and, where useful, aggregates or fingerprints of stable sets. Record the reference time and the source of that data. A number without scope or context is not enough to verify a recovery.
Invariants are conditions that must remain true both during and after the migration. They may include relationships between tables, uniqueness, allowed states, amounts that must be preserved, or consistency between database records and connected systems. For each invariant, add a reproducible query or procedure and an acceptance threshold. If the data can legitimately change during execution, define how to distinguish that activity from the migration’s effects.
In a PHP application, transformations can be implemented in console commands or worker processes rather than relying on a long-running web request. This choice does not eliminate concurrency risks or transaction limits: determine which unit of work can execute atomically and what to do if the process stops between two operations.
Design batches, checkpoints, and resumable execution
Divide the work into batches with explicit boundaries, for example, using a stable, ordered key. Avoid offset-based pagination if rows can change or disappear during processing; a continuation marker based on a key is usually more predictable. Batch size should balance transaction duration, database load, and ease of detecting failures.
After each batch, save a checkpoint with the job identifier, processed range, status, time, and validation results. Updating the data and advancing the checkpoint must be coordinated to avoid marking an uncommitted batch as processed. If both operations cannot be part of a transaction, design a reconciliation process that detects the intermediate state.
A resumable migration does not blindly reapply changes. Each operation must tolerate retries or check whether its effect already exists. In PHP, this can rely on transactions, unique constraints, and idempotent operations, depending on the database engine and data model. Also test deliberate interruptions: a deployment, exception, or lost connection should not leave the work without a known way to continue.
Record changes to locate effects and audit decisions
Assign a unique identifier to each run and record, at a minimum, the transformation, scope, batches, affected rows, errors, and recovery decisions. For changes that can be compensated, retain the necessary previous data or a secure reference to it. Do not indiscriminately log sensitive information; limit access, retention period, and content to what is necessary for recovery and auditing.
The log should make it possible to answer specific questions: which rows were attempted, which were committed, which failed, and which subsequent operation modified them. Combine technical logs with a business change history when necessary. Do not confuse traceability with a backup: the log should contain enough detail for its purpose and also needs protection against loss or alteration.
Choose whether to resume, compensate, or restore
Define signals and responses in advance instead of relying solely on intuition when an error occurs:
- Resume: if the failure is transient, invariants still hold, and committed batches are identified. Retry a limited number of times and monitor errors and load.
- Compensate: if the applied changes are known and a tested corrective operation exists. First stop new incompatible writes and confirm that compensation will not overwrite valid changes.
- Restore: if corruption is widespread, backup recovery has been validated, and the impact of losing or rebuilding subsequent changes is acceptable. Coordinate recovery with replicas and integrations.
- Stop and escalate: if the state cannot be determined, counts diverge without explanation, or compensation could cause further damage. Preserve evidence before taking action.
Set thresholds for pausing the work, such as an error rate above the permitted limit, a violated invariant, or a discrepancy in counts. Define who can authorize resuming and who decides on a restore. Sometimes the safest option is to isolate the affected flow and keep the system in a controlled state while investigating.
Validate and close the migration with a checklist
Completion of the process does not prove that the data is correct. Compare before-and-after counts against the expected scope, run business rules, and review relationships and outliers. Use sampling to inspect specific cases, but not as a substitute for complete checks when those are feasible. If external consumers are involved, also check their states and agree on how to reconcile discrepancies.
Before execution: classify transformations, confirm backup and recovery, test batches and retries with representative data, define invariants, stop limits, owners, and the operating window. Ensure the team can access the change log and that compensation or restoration procedures have been tested.
After execution: validate counts and rules, review errors and external effects, retain the execution log, and document any exceptions. Keep recovery information available for the agreed period and securely remove it when it is no longer needed. The migration is closed only when the results are verifiable and there is an explicit decision about any outstanding discrepancies.