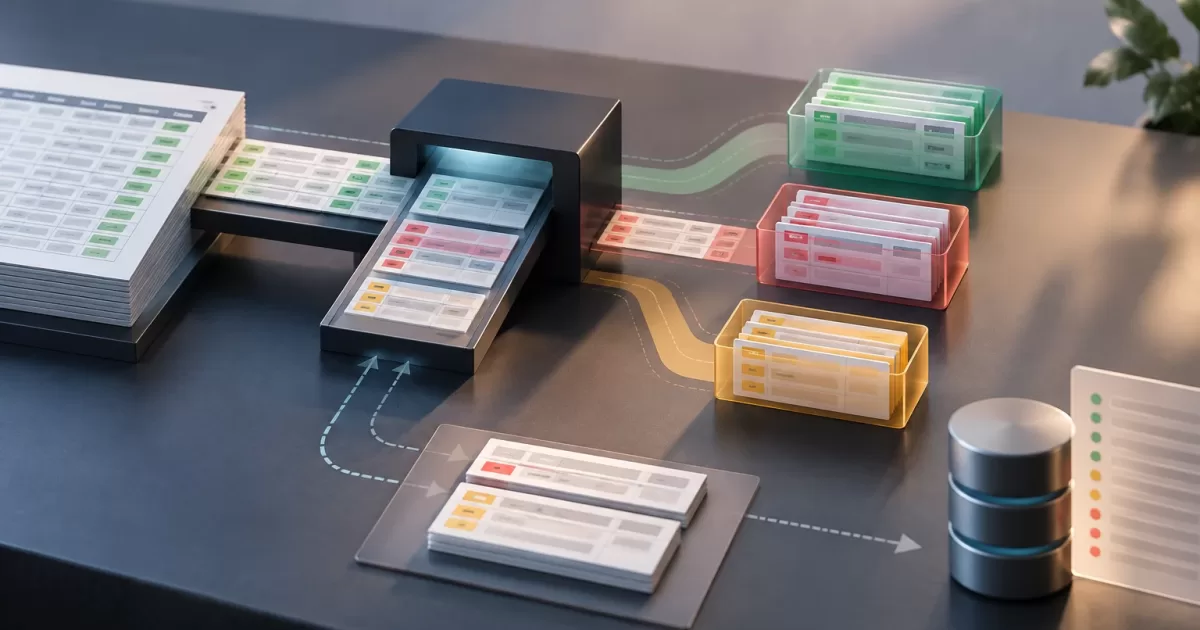
An enterprise import should not force you to choose between canceling an entire batch because of one defective row and importing questionable data. Data quarantine in PHP imports offers a third option: accept valid records, isolate those that need attention, and retain enough context to resolve them safely.
Quarantine is not simply an error folder or a table for storing failed rows. It is an operational workflow with classification rules, explicit states, controlled correction, and retries that do not repeat side effects. To design it, first agree on what “valid” means for the business and what actions each role can perform.
Classify errors before deciding what to do with each row
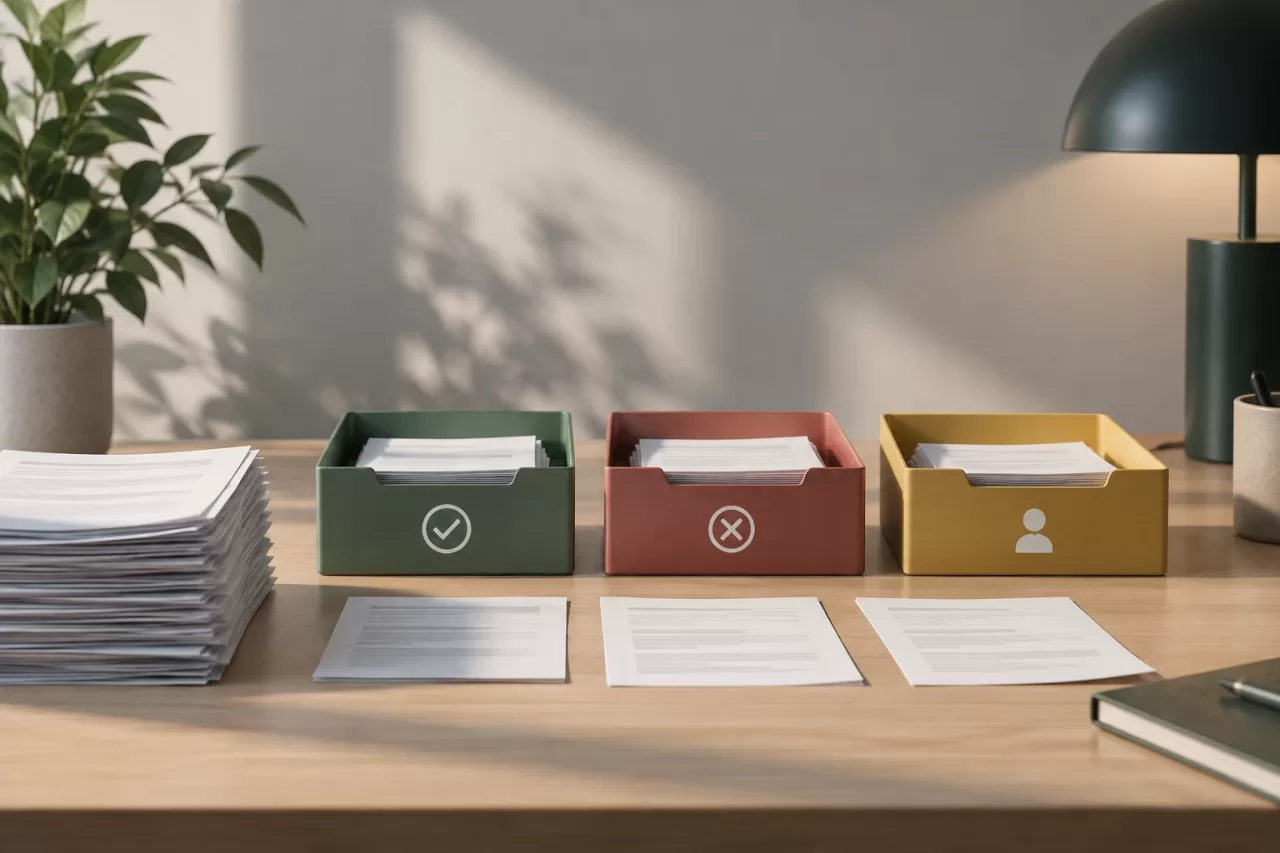
An import typically combines different checks. Separating them makes it possible to explain the outcome and decide whether a record can proceed, must be rejected, or requires human review.
- Structural validation: Checks basic format and content: required columns, data types, parseable dates, required fields, and reasonable limits. An unreadable file may prevent the batch from being processed; an invalid date in a single row normally should not.
- Business rules: Checks domain-specific conditions, such as a non-negative price, an active customer, or an allowed category. Some violations warrant rejection; others may depend on an operational decision.
- Conflicts with existing data: Detects, for example, an external identifier already associated with another record or an update based on an obsolete version. These conflicts cannot always be resolved by correcting the file; they may require reconciliation or review.
Define a policy for each error type. A missing optional field may allow a default value; an ambiguous identity should not be resolved by arbitrarily choosing a record. Avoid both overly permissive rules and classifying every defect as a fatal error. The decision should reflect the impact of accepting the data and the cost of stopping the batch.
Model explicit states and transitions
Use states with operational meaning instead of inferring the situation from empty fields or text messages. An initial model might include pending, accepted, rejected, and needs_review. Add states such as processing or resolved only if they correspond to actual transitions in your workflow.
Document what each transition allows. For example, a pending row is validated; if it passes the rules, it is accepted, and if it has a conflict that can be reviewed, it remains pending review. A corrected row can be validated again, but an accepted row should not be processed again as if it were new. Track the batch state separately: a batch can finish with some rows accepted and others quarantined, so “partially completed” describes the outcome better than a single success or failure indicator.
States should correspond to verifiable decisions. “Rejected” should mean that the business change was not applied; “needs review” indicates that a person must make a decision. If overwriting existing data is allowed, specify who can do so and under what conditions.
Keep the original and explain every decision
Store the row’s original input and, separately, its normalized values and validation result. This separation makes it possible to investigate discrepancies—for example, differences between a received date and its interpretation—without making the transformed version the only available evidence.
A persistence structure may include a batch identifier, row number, source, file reference, original content, state, detected errors, creation and resolution dates, and the responsible actor. Record reasons as stable codes and readable messages: a code such as customer_id_ambiguous helps filter and measure cases; the message should explain which data to review. Avoid relying on free-form text as the only classification logic.
Also retain the context needed to reproduce the analysis: the version or identifier of the rules used, the external identifier, and data relevant to the conflict. Do not store secrets or unnecessary personal data in technical logs. Define access controls and a retention period that reflect applicable sensitivity and obligations. If the full file may contain information that is not needed to resolve a row, limit its exposure.
Correct and retry without duplicating side effects
A safe retry starts by distinguishing the row from the attempt to process it. Assign each row a stable identity within its scope, for example, a combination of batch and row index or a validated external key. For repeatable imports, also define an idempotency key that can identify the same operation. The choice depends on whether reloading the same file should update data, ignore it, or create a new version.
When processing a row, apply the business write and state change atomically when possible: both operations commit together, or neither does. In PHP, a database transaction can protect changes that use the same connection; it does not, by itself, make a call to an external API atomic. For external side effects, use a strategy compatible with the receiving system, such as idempotency keys, a transactional outbox table, or a compensation designed for the case.
After a correction, rerun the relevant validations and retain the previous history. Do not delete the original error: add a new attempt with its result. If rules or reference data change, record which version was applied and avoid silently changing a decision that has already been accepted when it is retried. A retry should affect only the selected records and should not indiscriminately rerun the entire batch.
Design an operational and auditable review process
The review interface should help people make decisions, not merely display a technical exception. Include the received value, the reason, the affected field, relevant context, and, when safe, a proposed correction. Allow filtering by state, batch, error type, and age; make it clear which rows have already produced side effects and which have not.
Record who reviewed the case, when, which value they changed, the decision made, and the reason. Distinguish an operator’s correction from an automatic transformation. Apply permissions according to responsibilities: someone who can import a file should not necessarily be able to approve conflicts or alter accepted records. For high-impact changes, consider an additional approval.
Avoid making it easy for the tool to overwrite information without warning. Before accepting a correction, recheck uniqueness, permissions, and the record’s current state. If someone else has changed the data since the conflict was detected, present that condition for resolution instead of applying an obsolete update.
Test partial failures and recovery
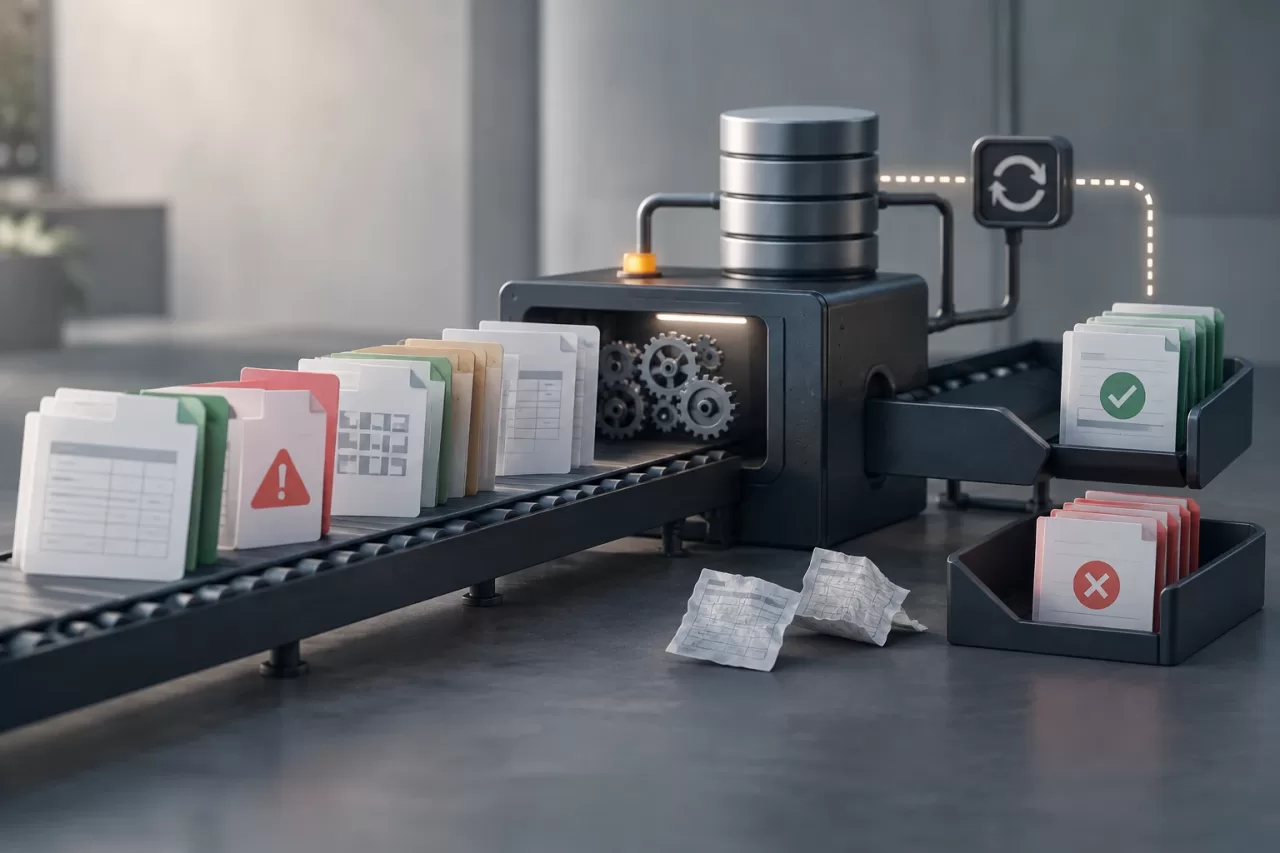
Tests should cover both the rules and the workflow’s behavior. Include files with a mix of valid and invalid rows, unexpected formats, conflicts, temporary database errors, and repeated retries. Verify that a rejected row does not prevent the others from being accepted if that is the agreed policy, and that a failure within a transaction does not leave partial side effects.
- Reprocessing a row with the same idempotency key does not duplicate records or external actions.
- Correcting a field allows a new validation without deleting the original or the history.
- An already accepted row is not applied again when another row is retried.
- Conflicts detected between review and resolution are not silently overwritten.
- Error messages make it possible to take action without exposing unnecessary sensitive data.
In production, monitor the volume and age of quarantined records, the most common reasons, the resolution rate, and retry failures. A sustained increase may indicate a change in the source system, an outdated rule, or unclear loading instructions. Quarantine works when it makes these causes visible and allows them to be resolved with control—not when it becomes an indefinite repository for exceptions.