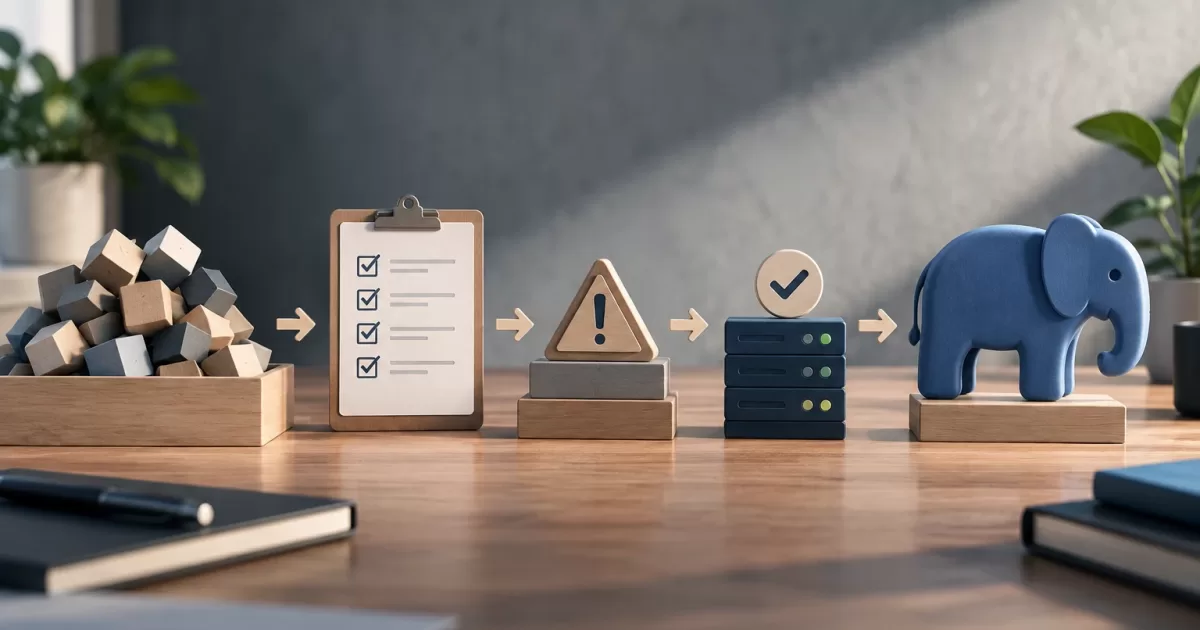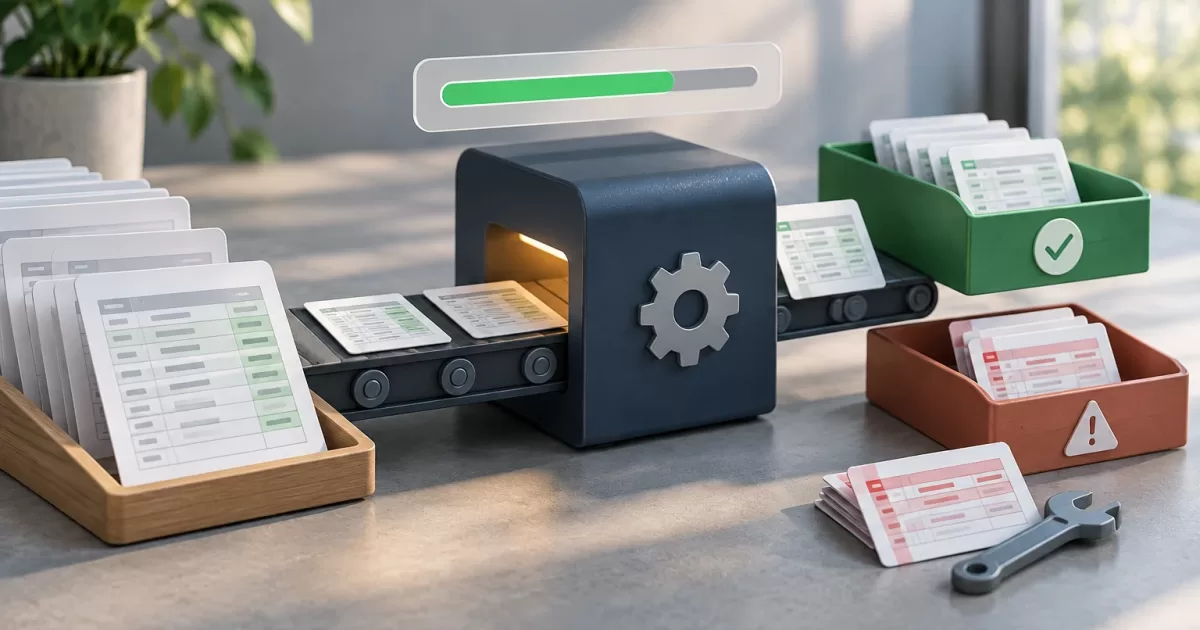
A large import should not depend on the user keeping an HTTP request open or leave them unsure whether the system is still working. A well-designed API turns the process into an identifiable, observable operation: it receives the file, validates its structure, processes the data, and reports the result, including errors that require correction.
Import progress tracking in PHP is part of the API contract, not a queue technology. It helps to separate three related concerns: which status the user can query, how the work runs in the background, and how to recover a task that fails.
Why Not Process the Entire Import in an HTTP Request
A synchronous request keeps the client waiting. For a large import, processing may exceed the limits of the web server, a proxy, or the client itself. If the connection is interrupted, it may also be unclear whether some records were modified.
One alternative is to accept the request, store the file somewhere the processor can access, register the operation, and return an identifier. The work runs afterward, outside the initial request. A queue can coordinate it, but it does not replace the persisted status that the API needs to expose.
The acceptance response confirms that the request was received, not that all the data was imported. It should therefore include a queryable identifier and an initial status. Validating the file size and format can reject unsuitable files, but does not guarantee that every row is valid.
Define States, Transitions, and Results
Agree on a bounded set of states and verifiable transitions. One possible lifecycle includes received, validating, and processing, with terminal outcomes such as completed, completed_with_errors, failed, and cancelled. The names may vary; their meanings must be unambiguous.
completed_with_errors can indicate that valid rows were applied and the remaining rows are available for correction. Reserve failed for a situation that prevents processing from continuing or makes it impossible to determine a reliable outcome. Do not declare success just because the technical process finished if some data was not applied.
- Define which states are transient and which are terminal.
- Document who can initiate each transition and under what conditions.
- Separate general errors from errors associated with a row.
- Include creation, start, and end timestamps when they help explain the outcome.
- Do not expose stack traces, internal messages, or sensitive data in public responses.
Protect transitions against duplicate executions and out-of-order updates. A terminal operation must not return to processing because of a late notification. Updates conditioned on state or version are common ways to prevent concurrent overwrites.
Separate File Receipt from Row Validation
When receiving a file, check permissions, file size, file type, and required metadata. Initial validation can check required columns and structure. If the file cannot be parsed, reject it or end the operation before applying partial changes without a defined policy.
Row-level validation takes place during processing. It may uncover nonexistent references, invalid values, or conflicts with current data. Decide whether valid rows are applied even when others fail, or whether the operation must be atomic and rolled back. The choice depends on the domain and side effects, and must be clear to the user.
Identify each row consistently using a source key or, if none exists, a reference tied to the batch. Store an error code and an understandable message. For large files, return errors in paginated responses or through a protected downloadable result rather than repeating them with every status query.
Design a Workflow for Correcting and Resubmitting Errors
The product can let users correct the entire file and upload it as a new import, or resubmit only failed rows. The first option is easier to explain, but requires recognizing records that were already applied when the file is processed again. The second reduces repeated work, but requires retaining source keys and associating each new attempt with the initial import.
For partial resubmission, provide an explicit action that accepts only failed or unconfirmed rows along with the corrected data. Do not rely solely on the line number: the user could change the file's order or structure. Preserve the previous attempt's outcome for auditing and validate the submitted data again.
Preventing duplicates requires a stable identity for each record. This could be an external identifier or a generated, persisted key for the row. Apply an appropriate unique constraint and define whether a repeat should update the existing record, be rejected, or be ignored. In all cases, already confirmed rows must not trigger side effects again. Idempotent operations and per-row or per-batch transactions help maintain this guarantee.
Publish Progress and Control Status Queries
Report the number of units processed and the total when it is known. Add the current stage—for example, validation or application—if it helps explain a wait. If the total is not yet known, report the stage without inventing a percentage. A percentage can be misleading if different phases take very different amounts of time.
It is not necessary to persist an update for every row. Batch updates according to their cost and the usefulness of the information, and avoid unlimited client polling. The interface can space out queries and stop them when it receives a terminal status. Notifications can also be used, but it must still be possible to retrieve the current status after reloading the page or losing connectivity.
Authorize every query and check that the requester can access that specific operation. A hard-to-guess identifier does not replace permissions. Apply the same checks to errors and downloadable files, and define how long they are retained.
Distinguish Retrying, Resuming, and Cancelling
Retrying means running again something that failed; resuming means continuing from a saved point. A retry can repeat rows or side effects if processing is not idempotent. Before offering it, determine what was confirmed and how duplicates are detected.
Resuming requires saving enough information to identify the last confirmed work and avoid applying what has already been processed again. If the source data has changed or a consistent continuation cannot be guaranteed, it is safer to create a new import than to claim that processing is being resumed.
Cancellation does not automatically undo changes that have already been applied. Define whether it is accepted only before processing starts, checked between batches, or handled through compensating actions. Communicate whether processing stopped before any work was done, whether partial changes remain, or whether it was already too late to interrupt.
Data Model and PHP API Workflow
An initial model might include an imports table with id, owner_id, status, stage, total_rows, processed_rows, success_rows, error_rows, file_key, created_at, started_at, finished_at, and version. In import_rows, store import_id, source_key, row_number, status, and attempt_count. A unique constraint on import_id and source_key identifies a row within the batch. An import_errors table can store the key, code, and a user-safe message.
An illustrative REST workflow accepts the file through POST /api/imports and responds with 202 Accepted and {"id":"imp_8f2a","status":"received","status_url":"/api/imports/imp_8f2a"}. The client queries GET /api/imports/imp_8f2a; a response during processing might be {"status":"processing","stage":"applying","total_rows":1200,"processed_rows":450,"success_rows":438,"error_rows":12}. To retrieve errors, use a paginated endpoint such as GET /api/imports/imp_8f2a/errors?limit=50&cursor=....
If resubmitting only failed rows is allowed, POST /api/imports/imp_8f2a/retry-errors can receive source keys and corrected data. It must reject keys already recorded as applied, or handle them according to an explicit idempotency policy, and return the identifier of the new attempt. The endpoint must not obscure the fact that it creates a related attempt rather than deleting the previous history.
In PHP, the controller registers the operation and responds without processing the entire file in the request. This snippet is PHP 7-style pseudocode: it does not use named arguments, and setJsonBody() represents a custom adapter, not a standard PHP method or one that is portable across frameworks. In a real application, replace it with the response mechanism provided by the implementation or framework in use:
$import = $imports->create(
    $user->id,
    $storedFile->key,
    'received'
);

$dispatcher->dispatch(new ProcessImport($import->id));

$response->setStatusCode(202);
$response->setJsonBody(array(
    'id' => $import->id,
    'status' => 'received',
    'status_url' => '/api/imports/' . $import->id
));

return $response;
The example shows the separation between acceptance and execution, but does not by itself guarantee that the work is durably registered. Coordinate persistence of the operation and dispatch of the work so that a failure between the two steps does not leave an import unprocessed. Depending on the infrastructure, a transaction with the outbox pattern or another reliable mechanism can be used.
Tests and Checklist
Test valid and invalid transitions, malformed files, partial errors, duplicate requests, and interruptions. Verify that a terminal operation does not publish further progress, that counters are consistent, and that error pagination enforces permissions. Include the case where an already-applied row appears in a resubmission: there must still be only one record, and no side effect must be repeated.
- Can the user distinguish receipt, processing, and the final outcome?
- Is it defined whether the user corrects and uploads the file again or resubmits only failed rows?
- Do stable keys prevent records that have already been imported from being duplicated?
- Do the counters reflect confirmed work and update at a reasonable frequency?
- Do status queries and error downloads require appropriate permissions?
- Do retrying, resuming, and cancelling have defined, verifiable effects?
- Have partial failures, concurrency, and data retention been tested?
An observable import is more than a progress bar. It needs understandable states, queryable results, and a correction policy that does not reapply confirmed records. Separating this contract from the execution mechanism makes it possible to evolve processing without leaving the user uninformed.