
An integration can respond successfully and still leave different data in two systems. A request may time out after the external system has saved the change; an event may arrive late; or a local update may modify a field that the other system also controls. That is why, in addition to synchronizing events, it is useful to be able to compare states and resolve discrepancies deliberately.
Data reconciliation between systems in PHP is a periodic or on-demand process that identifies differences between related records, determines what they mean, and proposes or applies an action. It does not mean indiscriminately copying one system over another. To avoid losing valid information, you need to define the authority for each data item, preserve evidence of the comparison, and protect the application from repeated or bulk corrections.
Define which system has authority before comparing
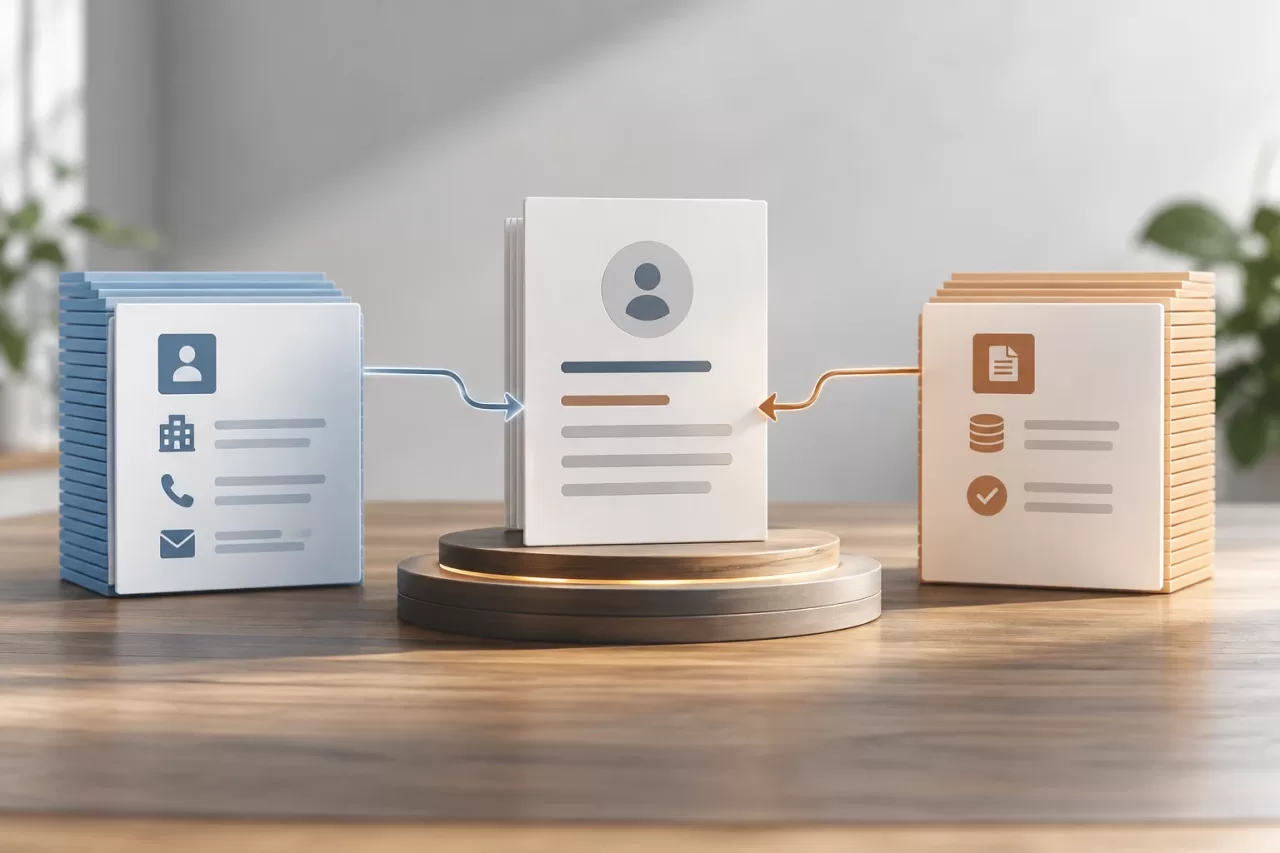
The source of truth is not always the same for an entire entity. The CRM may be responsible for the trade name and contact details, while the billing system controls payment status and the validated tax ID. If you designate an entire system as authoritative without reviewing the fields, reconciliation may replace correct information with an outdated or incomplete copy.
Document ownership of the fields being exchanged. For each field, record which system can originate changes, which one takes precedence in a conflict, whether the value can be null, and which transformations are acceptable. It is also useful to distinguish between editable and derived fields: a calculated total, for example, may need to be regenerated from its components rather than copied.
- Authority by field: define which system determines its value and what to do if both systems show changes.
- Merge rules: specify whether missing data can be filled in without replacing existing data.
- Exceptions: identify conflicts that require approval, additional validation, or intervention by the responsible team.
When there is no safe rule, the right action is to flag the conflict for review, not to arbitrarily choose the record with the most recent date. Clocks can differ, and a timestamp alone does not prove that a change is legitimate.
Make the comparison reproducible
A useful comparison needs to identify the same record on both sides. Use a stable shared identifier or an explicitly maintained mapping table. Do not rely solely on names, email addresses, or other fields that can change, be repeated, or be normalized differently. If no unambiguous relationship can be found, classify the case as awaiting linkage rather than approximately matching records and merging them.
Compare values normalized according to documented rules—for example, whitespace, capitalization, or date formats. Also preserve the original value, because normalizing for comparison does not authorize changing the persisted data. Be careful with time zones, decimal precision, empty values, and the difference between a missing field and a present field with a null value. Treating these states as equivalent can hide relevant changes.
For large data sets, define a work window and a watermark, such as a modification date or pagination cursor. Save the checkpoint only after the batch has been processed consistently. If the provider does not offer reliable markers, a less frequent full scan or a combination of sampling and targeted reconciliation may be safer than pretending to have incremental processing that the API does not guarantee. The strategy depends on the actual limits, stability, and guarantees of each system.
In PHP, separate data retrieval from comparison and result persistence. For example, a comparison function can receive two normalized representations and return a list of typed differences, without making remote calls or updating records. This separation makes it possible to test rules with controlled cases and review proposals before enabling writes.
Classify discrepancies and decide how to respond
Not every difference indicates an error, and each category requires a different policy. Explicit classification improves diagnosis and prevents one destructive rule from being applied to different situations.
- Missing: the record exists in one system but not the other. Check whether this is a recent creation, a legitimate deletion, a filter, or a pagination failure.
- Duplicate: multiple records appear to correspond to one entity. Do not automatically choose one without a verifiable identity rule.
- Incompatible change: both sides have changed a field controlled by both. Apply an ownership policy or send the conflict for review.
- Invalid data: the value does not meet the expected format or constraints. Quarantine it and prevent it from being propagated.
- Timing difference: the discrepancy may be caused by delivery or processing delays. Retry or wait for a defined window before declaring a persistent conflict.
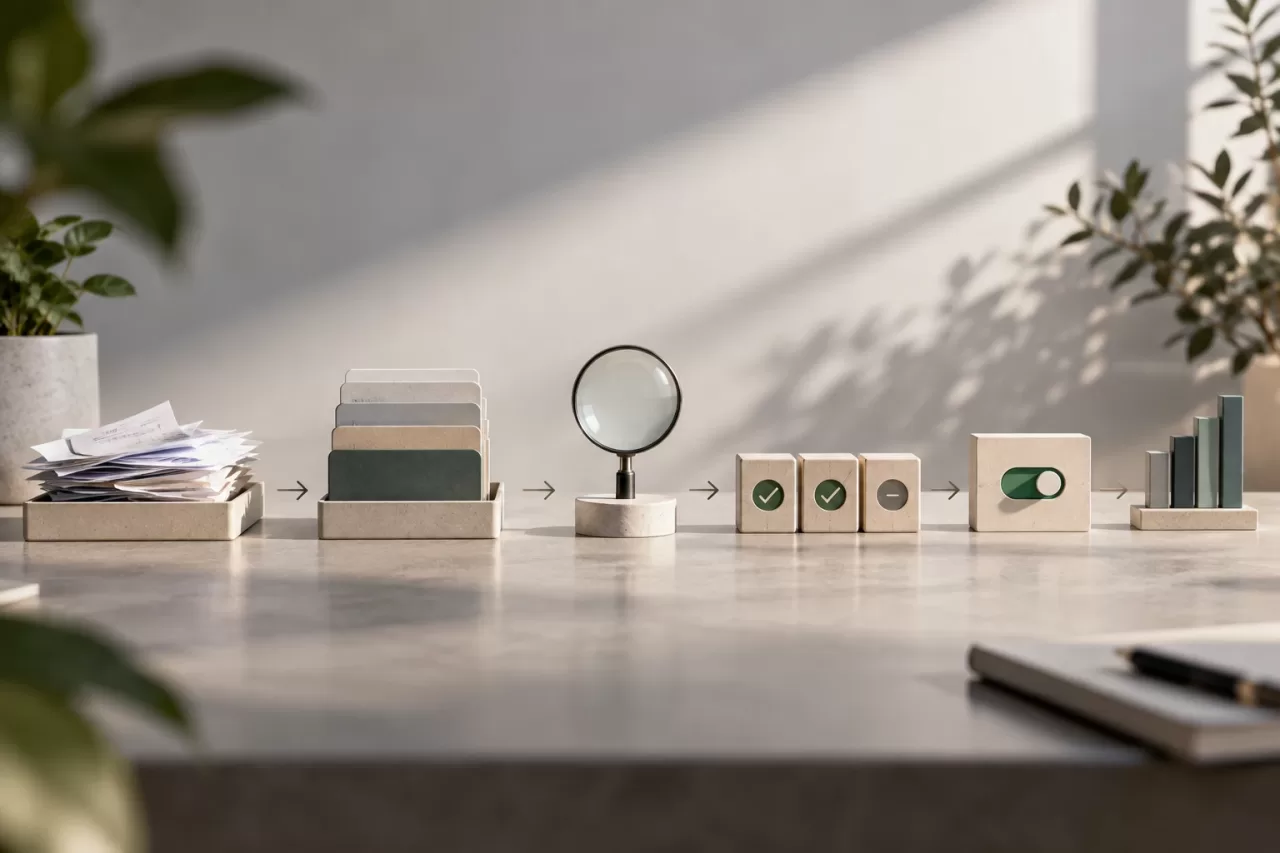
Separate three stages: detection of the difference, decision on what to do, and application of the change. A proposal may be to update a field, create a mapping, request a review, or do nothing. Keeping these stages separate makes it possible to start in read-only mode and understand what would change before enabling automatic corrections.
Apply changes without causing new damage
Automate only cases covered by clear, verifiable rules. For all others, provide a review queue with the entity identifier, observed values, the rule that would be triggered, and the proposed action. The interface or operational process should allow the proposal to be accepted, rejected, or escalated, and record who made the decision when appropriate.
Design operations to be idempotent: processing the same discrepancy again must not create duplicates or alternate values indefinitely. Before writing, check that the record is still in the expected state. If it has changed since it was read, stop the update and compare again. When the external API allows it, use versions, conditional writes, or idempotency keys; do not assume they exist without verifying.
Limit scope with small batches, per-run change limits, and pause options. A correction that exceeds the expected volume should stop or require authorization, not continue silently. For high-impact changes, record a possible compensating operation, but do not present it as a guarantee of rollback: subsequent changes or external effects may be impossible to undo.
Log each run so it can be investigated and repeated
Store a run ID, its start and end times, the range or cursor processed, the systems queried, the result by category, and any errors. For each discrepancy, preserve the correlation key, relevant values or a protected representation, the rule evaluated, the proposed action, and the application result. This makes it possible to explain why a decision was made and distinguish an integration failure from a genuine conflict.
Protect the logs: they may contain personal data, indirect credentials, or business information. Avoid dumping full payloads when specific fields will suffice, restrict access, and define retention. Include references to source records and observation times to facilitate investigations without turning the log into an uncontrolled second database.
Retry only transient failures, with limits and backoff. Log retries and separate permanent errors—such as invalid data or insufficient permissions—to prevent loops that repeat the same problem. A run must be resumable from a known checkpoint, rather than depending on the PHP process remaining active indefinitely.
Checklist before automating
- Is authority defined for each field, including how to handle nulls and deletions?
- Do identifiers link records unambiguously, and are duplicates handled?
- Have pagination, delays, API limits, retries, and concurrent changes been tested?
- Are differences classified, with exceptions sent for review or quarantine?
- Can the comparison run in read-only mode and show its proposed actions?
- Are writes idempotent, conditional on the expected state, and limited by volume?
- Are decisions and results logged with appropriate data protection and access controls?
- Have representative data been used in tests, including conflicts, empty values, duplicates, and partial failures?
Start by observing and classifying, not correcting. After validating the rules against real data and reviewing the proposals, enable automation only for low-risk discrepancies. Keep a way to pause the process and periodically review false positives, unresolved cases, and changes in external systems. This turns reconciliation into a repeatable operational control, rather than a synchronization process that hides conflicts until someone discovers their consequences.


