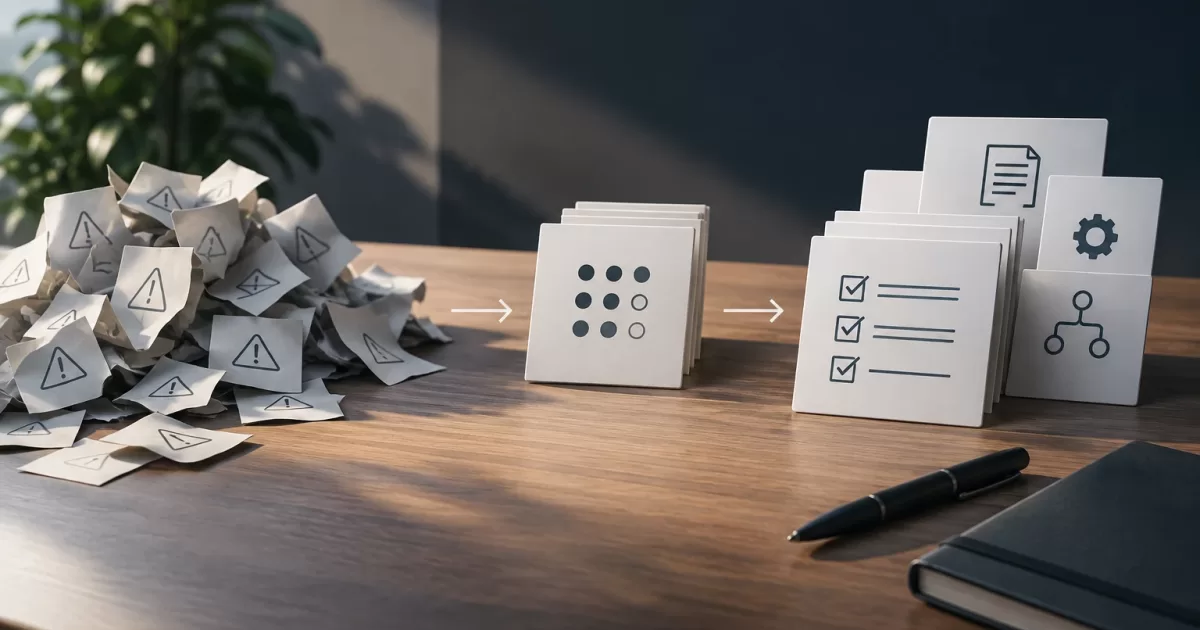
When support receives several similar requests, the usual response is to ask for a change. However, repetition alone does not prove that a new requirement exists: it may point to a defect, a confusing interface, a lack of training, or a poorly handled exception. Changing a PHP application before understanding the cause can automate the problem or introduce a rule that does not reflect the actual work.
Turning recurring issues into software requirements means moving from individual accounts to a verifiable decision: who needs what outcome, under which conditions, and with what exceptions. This process helps product, operations, and development agree on scope before estimating and changing the code.
Why a Repeated Issue Is Not Automatically a Requirement
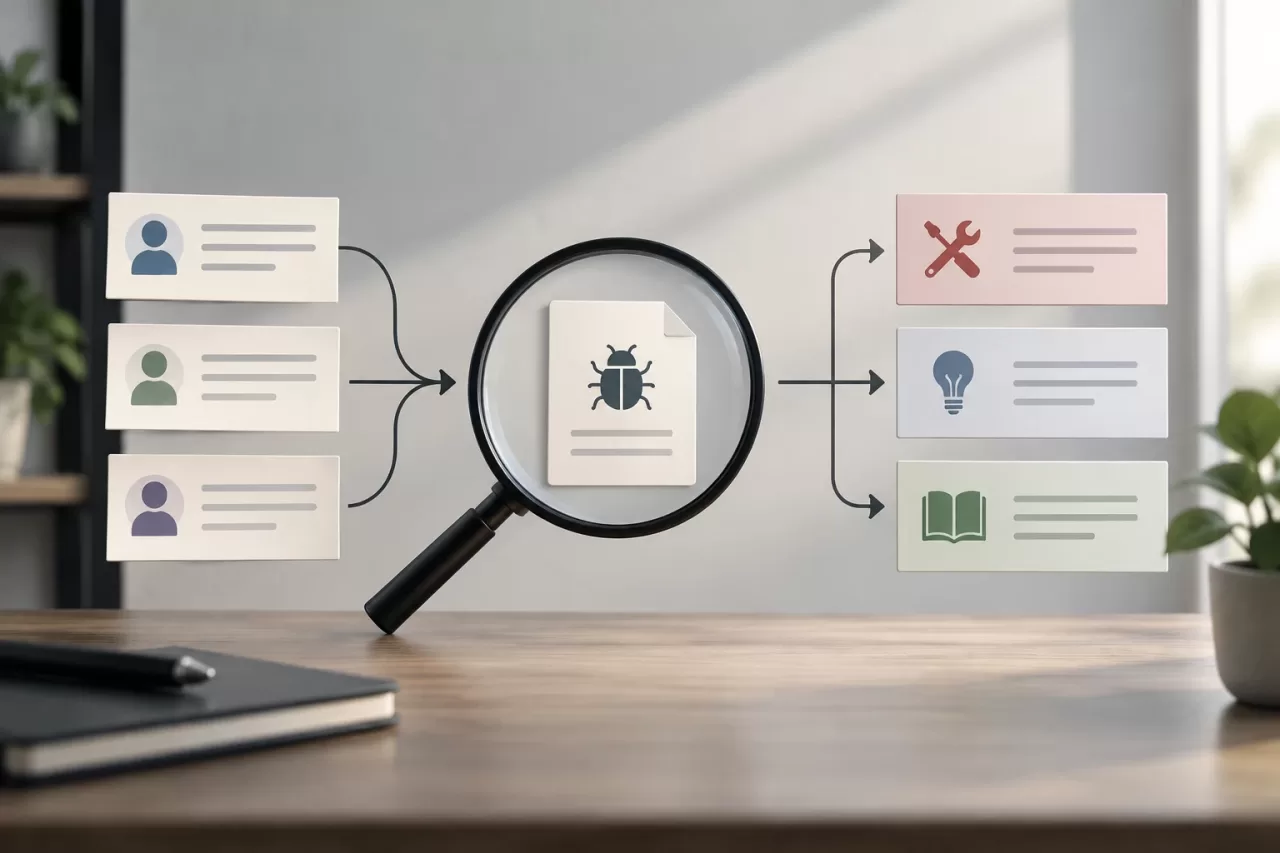
An issue describes something that happened; a requirement expresses a capability or constraint the system must meet. For example, several users asking for help correcting an invoice might be encountering the same calculation defect. They might also be unaware of an existing feature or working with a procedure that is not documented.
Counting requests without classifying them can distort priorities. One user may open several tickets about a single problem, while an important risk may appear only once. Group issues by cause and affected outcome, not just by similar wording or ticket count.
Classify: Defect, Training, Exception, or New Need
Before proposing an improvement, identify what kind of situation you are seeing:
- Defect: The system does not meet an already agreed rule. Compare actual behavior with the specification, logs, and reproducible cases.
- Lack of training or clarity: The capability exists, but users cannot find it or interpret the workflow differently. Review instructions, labels, and steps.
- Exception: A legitimate case does not fit the usual workflow, such as a partial refund or an after-hours approval. Determine whether it is a valid exception and who can authorize it.
- New need: The process has changed, or a capability that was not part of the expected behavior is missing. Its value, scope, and consequences need to be assessed.
The classification may change as you investigate. Do not make a decision based only on the ticket title: ask what the person was trying to accomplish and what outcome they needed.
Gather Context and Evidence to Understand the Case
A useful report reconstructs the journey, not just the final error message. Record the role of the person performing the task, the goal, preceding steps, relevant data, the outcome obtained, and the expected outcome. Add frequency, operational impact, and available evidence, such as a screenshot, an operation ID, or a technical log.
In PHP applications, the team can correlate the account with logs, API responses, server-side validations, and persisted data, always applying appropriate permissions and privacy controls. Avoid copying personal information or credentials into tickets; use anonymized data or secure references. Evidence helps reproduce the issue, but it does not replace an explanation of the business rule.
Practical questions for support or product:
- Who performs the task, and what permissions do they have?
- What were they trying to complete, and why?
- What steps and conditions preceded the problem?
- What did they expect to happen, and what actually happened?
- Are there examples that worked and others that failed?
- What is the impact, and is there an acceptable manual alternative?
Find the Business Rule and Record Its Exceptions
Several examples can help formulate a hypothesis, but they are not enough to declare a rule. Compare the cases with the people who carry out the process and those responsible for its policies. Look for the condition that changes the outcome: operation status, customer type, amount, deadline, permissions, or the relationship between records.
Write the rule in direct language and state its limits. For example: “A request can be approved if it is complete and belongs to an open period.” Then clarify what “complete” means, who determines whether the period is open, and what happens to corrected or duplicate requests, or requests received at closing time. If the responsible people do not agree on these answers, there is not yet a stable specification.
Exceptions are not details to hide in a note. They may require different permissions, human review, a recorded reason, or a separate workflow. If an exception is rare but high-impact, its low frequency does not make it irrelevant.
Write Observable Acceptance Criteria
A requirement can be validated when it describes outcomes someone can verify. Avoid phrases such as “handle correctly” or “make it easier” unless they are accompanied by concrete conditions. The criteria should cover the normal workflow, invalid data, permissions, and the identified edge cases.
A simple way to write them is: “Given [context], when [action], then [observable outcome].” For example: “Given an authorized user and an open period, when they submit a complete request, then the system records it with a pending status and displays its ID.” Add another criterion for a closed period and specify whether the request is rejected, saved as a draft, or requires approval.
For a PHP application, the criteria can guide unit tests for domain rules, integration tests for persistence or APIs, or functional tests of the workflow. Do not prescribe an implementation before understanding the need: a rule may belong to validation, authorization, a state transition, or a process change.
Prioritize and Validate with Product, Operations, and Development
Prioritize based on impact, risk, scope, and opportunity cost, not just ticket volume. Clarify how many people or processes are affected, the consequences of the failure, whether a temporary control exists, and how much work is needed to cover the exceptions as well. An infrequent problem may deserve priority if it causes data loss or noncompliance with an obligation.
Before estimating, product should confirm the outcome and boundaries; operations should confirm that the workflow describes actual practice; and development should confirm that the criteria are technically clear and testable. If questions remain, agree on a bounded investigation, a manual test, or observation of the process. Do not turn a hypothesis into automation just to close tickets faster.
After the change, validate the criteria with representative cases and monitor whether the original cause becomes less common without creating new blockers. Implementation, deployment, and user activation are distinct decisions: if the risk warrants it, a release can be gradually exposed with metrics and a rollback option. Document what counts as success and who decides whether to stop or adjust the delivery.
A Brief Template for Turning an Issue into a Decision
Use this form as a starting point and complete only what you can support with evidence:
- Issue group and period: Related tickets, dates, and the criteria used to group them.
- Person and task: Role, goal, and operational context.
- Observed behavior: Steps, relevant data, and actual outcome.
- Expected outcome: The need as expressed, without proposing a solution yet.
- Classification and hypothesis: Defect, training, exception, or new need; cause to be confirmed.
- Rule and exceptions: Condition that determines the outcome, rule owner, and known limits.
- Impact and alternative: Consequences, scope, and temporary procedure.
- Acceptance criteria: Normal and invalid cases, permissions, and edge cases with observable outcomes.
- Decision and validation: Priority, owners, planned tests, and a signal for reviewing the outcome.
If the rule, exceptions, or expected outcomes cannot be completed, the right conclusion may be to investigate, improve training, or fix the existing defect—not to create a new feature. This distinction turns recurring support issues into clearer product decisions and reduces changes based on assumptions.