When a multi-step process fails, running it again from the beginning can repeat effects that have already occurred: creating two orders, sending two notifications, or importing the same record twice. Partial recovery of failed PHP processes means determining which steps are confirmed, which can be repeated safely, and which require compensation or human review.
The decision depends on the semantics of each operation, not just on where an exception occurred. For example, a missing response from an API does not prove that the external system rejected the request. The process may have completed, and the connection may have failed before PHP received the result. Designing for this case avoids mistaking an interrupted execution for one that never happened.
Choosing Between Retrying, Resuming, and Compensating
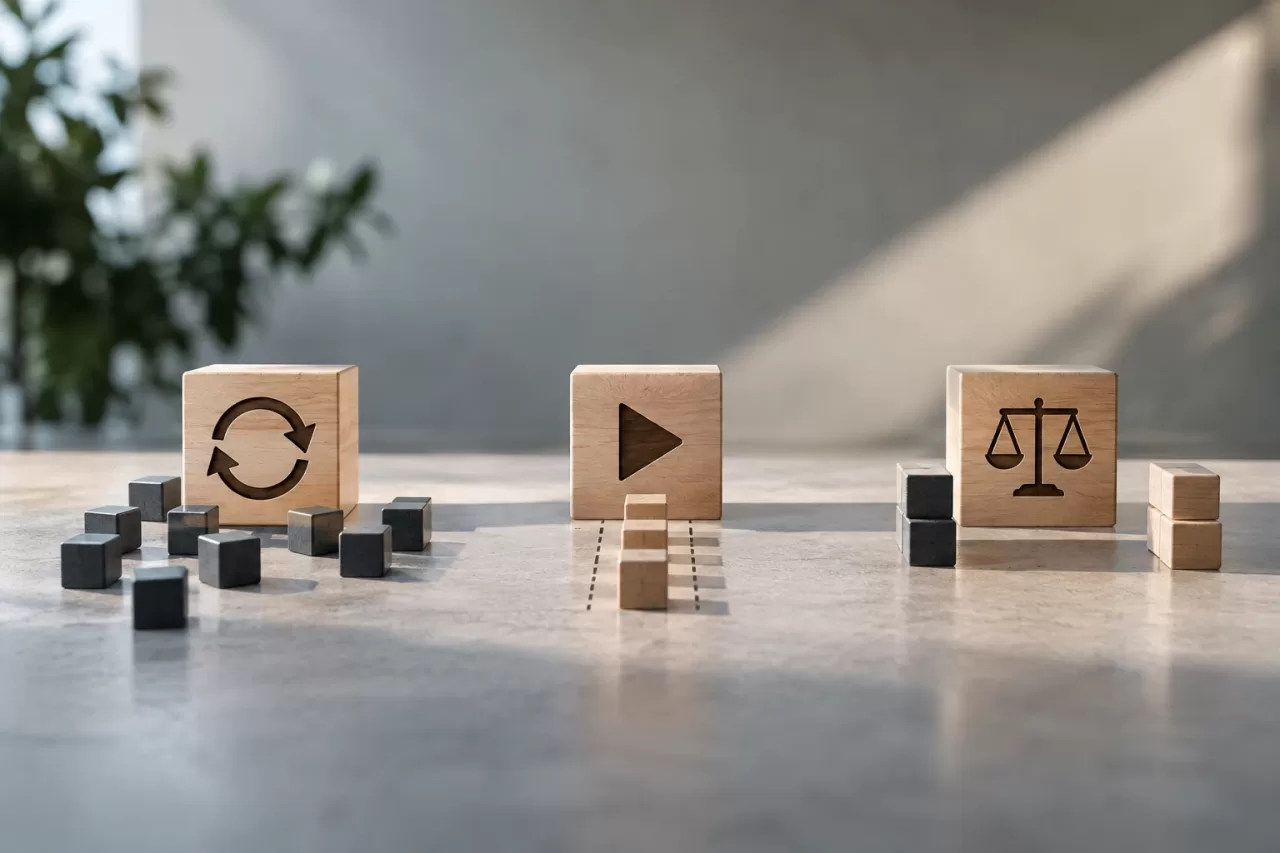
A full retry runs every step again. It is appropriate when the entire workflow is idempotent—repeating it leaves the same final state—or when no external effects have occurred yet. If neither condition can be guaranteed, repeating the workflow without inspection is risky.
Resuming means continuing from the first unconfirmed step. It requires recording the state of the steps and their results, as well as being able to retrieve or verify the effect of a call whose result is ambiguous. It does not mean skipping everything that appears to be complete: persisted evidence is required.
Compensating means performing an action that counteracts an earlier effect, such as canceling a reservation. It does not always restore the exact original state: a notification that has already been sent cannot be withdrawn, and a captured payment may require a refund with its own timing and record. For this reason, compensation is an explicit business operation, not an automatic database rollback.
Modeling Steps with Persisted States and Results
Represent the workflow as a sequence or state machine whose steps have stable names, identifiable inputs, and persisted results. An initial model might include states such as pending, running, succeeded, retryable, failed, and manual_review. Define the allowed transitions and prevent a process from moving to a terminal state without saving the necessary evidence.
A record for each process can include a stable identifier, workflow type, overall state, process definition version, start and update dates, attempt number, and reason for the last transition. Each step should store its state, an operation identifier, timestamps, and a reference to the relevant result. Persist only the information needed to resume or explain the outcome; do not indiscriminately copy complete API responses or secrets.
In PHP, the coordinator can separate state transitions from step execution. The update must be atomic when multiple workers can claim the same job: use a transaction or an appropriate locking mechanism, and record who claimed the process and until when. A lock with an expiration must allow abandoned jobs to be recovered without treating a step left halfway through as complete.
Defining Checkpoints Without Assuming “Exactly Once”
Save a checkpoint after every result the system can reliably confirm. For local operations, this can be a transaction that saves the business change and the step state together. For an external call, there is no shared transaction between the database and the provider: the process can stop after the provider acts but before PHP records the response.
At this boundary, use an idempotency key if the provider supports one, derived from a stable process and step identifier. If there is no support, query the remote state using an operation identifier before repeating the request. When neither idempotency nor reliable querying is available, treat the result as ambiguous and send the case for review. A timeout is not enough to conclude that the operation did not occur.
For asynchronous tasks, the transactional outbox pattern lets you save the local change and the pending message within the same transaction. A worker then delivers the message; the consumer must also tolerate duplicates, for example, by storing the identifiers it has processed. These mechanisms reduce inconsistencies, but they do not automatically turn an entire distributed integration into an atomic operation.
Setting Limits for Reruns and Compensation
For each step, define which errors are transient, which are permanent, and which leave the outcome unknown. Transient failures may allow retries with exponential backoff and jitter; set a maximum number of attempts and a total time limit. Validation or permission errors are unlikely to improve with retries: it is better to stop the workflow, fix the cause, and decide whether another run is appropriate.
For each external effect, document whether it can be repeated, queried, compensated, or not reversed. Preserve the result when the operation is valid and repeating it would be more harmful than the partial state; compensate only when a safe and authorized business action exists. Stop and escalate when the available data cannot establish what happened, compensation also fails, or the action has a financial, legal, or customer impact that requires approval.
A compensation policy must specify the order, conditions, owner, and expected outcome. Record compensation as a new step linked to the original effect instead of deleting its history. This allows operations teams to distinguish between an action that was never performed, one that was performed, and one that was compensated.
Giving Operations Teams Controls and Context to Act
The console or operational procedure should show the overall and per-step states, the latest classified error, the number of attempts, external references, and the permitted action. Avoid offering a generic “retry everything” button. Present bounded options: retry an idempotent step, query the remote state, perform compensation, or escalate.
Protect these actions with role-based authorization; require additional confirmation for sensitive effects, and record who acted, when, what they chose, and why. If rerunning changes input data, require a new execution or an explicit review instead of silently changing the input of a historical process.
To diagnose issues without exposing sensitive information, retain correlation identifiers, error codes, process version, and the references needed to query source systems. Redact tokens, personal data, and full payloads. Also define how long records are kept and who can access them. A useful trace explains what happened without becoming an unnecessary copy of business data.
Testing Failures and Rolling Out Recovery Gradually
Test interruptions at specific points: before executing a step, after the provider acts but before the response is saved, during compensation, and while two workers try to claim the same process. Verify that the state remains consistent in each case, effects are not duplicated, and manual actions are audited.
Include tests for ambiguous responses, repeated idempotency keys, invalid data, retry limits, and workflow version changes. Integration tests with mocked dependencies can reproduce controlled failures; when the real provider behaves differently, also validate the contract and query mechanisms in an appropriate environment.
For an existing workflow, start by classifying its steps by reversibility and idempotency. Then persist the state of a limited stage, implement recovery for the highest-risk failures, and observe pending cases before expanding the scope. Do not delete or reset historical records to make the rollout easier: preserve traceability and define how to interpret processes created with earlier versions.
Recovery Implementation Checklist
- Does each step have identifiable inputs, a persisted state, and a verifiable result?
- Is it known which calls are idempotent and what to do when their results are ambiguous?
- Are there limits on attempts and time, and are errors classified?
- Are compensations defined as business actions, with an audit trail and an owner?
- Can operations teams query and act with appropriate permissions, without accessing unnecessary data?
- Have failures between steps, concurrency, reruns, and failed compensations been tested?
- Is there an escalation procedure for cases where it is not safe to resume automatically?
The practical principle is to preserve enough evidence to decide what to do next and stop automation when that evidence is insufficient. Safe recovery does not try to hide that a failure occurred: it makes explicit what was completed, what remains pending, and who can resolve it.