A continuous integration (CI) pipeline should answer a specific question: can this change be incorporated into the shared codebase without introducing known defects or breaking agreed requirements? To answer it, define repeatable checks, order their execution, and make sure every failure provides useful information.
CI does not mean automatically deploying every change. It is the practice of integrating changes frequently and validating them automatically. Continuous delivery continually prepares a deployable release; continuous deployment adds automatic release to production when the established conditions are met. An application can have CI without automating delivery, or automate it up to a test environment while retaining an approval step before production.
Define the pipeline contract
Before choosing tools, specify what the run receives, what it must produce, and what conditions cause it to fail. A useful configuration documents at least:
- Inputs: the change being validated, the relevant configuration, and the dependencies declared by the project.
- Environment: the system and runtime requirements, PHP configuration, and services needed for testing. It should be sufficiently similar across runs for results to be comparable.
- Output: the final status, test and analysis reports, and, where applicable, an identifiable artifact that can be validated later.
- Failure conditions: which errors block integration, which generate warnings, and who can approve a temporary exception.
Installation should start from the versioned dependency configuration and honor the lock file, rather than silently resolving new versions on each run. This reduces one source of differences between developers and CI. You should also declare the platform and extension requirements the application expects, and check that the runtime environment satisfies them.
Avoid making the pipeline depend on local files, personal services, or undocumented manual steps. If a check needs a database, cache, or other service, define how it is started, what data it needs, and how it is cleaned up. The contract does not have to imitate production completely, but it should make explicit any differences that could affect the result.
Order checks by cost and detection capability
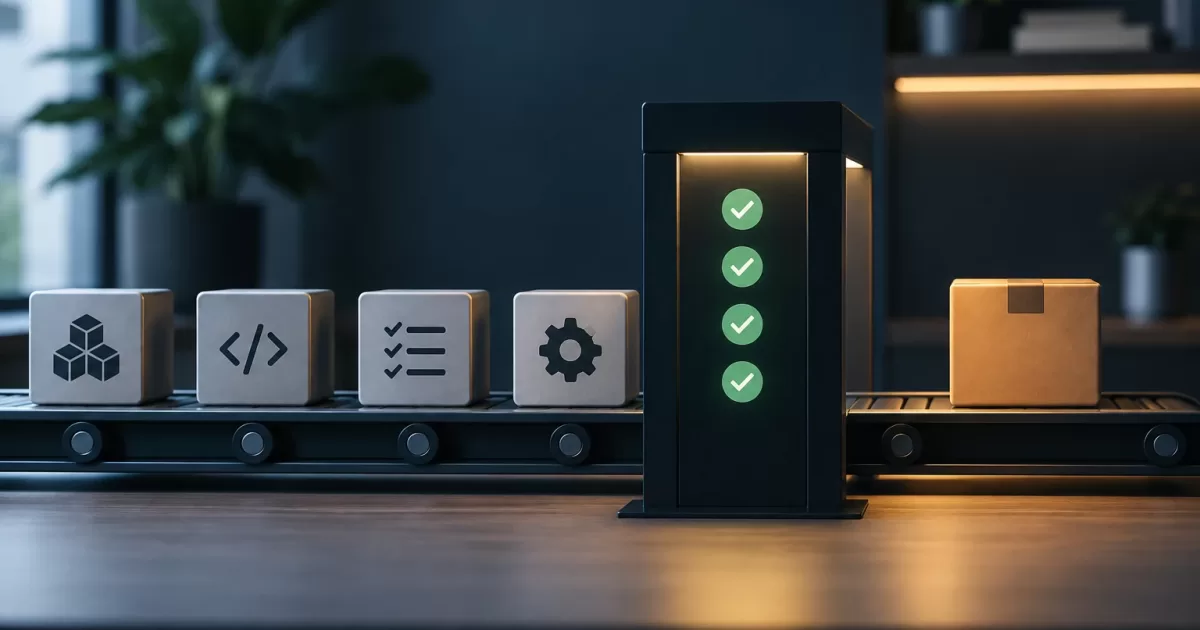
A practical sequence starts with fast validations and ends with those requiring more time or infrastructure. The priority is not to accumulate tasks, but to detect problems as early as possible without losing significant coverage.
- Reproducible installation: resolve dependencies from the project's definition and lock file. If this fails, the rest of the results are not reliable.
- Formatting and conventions: verify agreed formatting or style rules. These checks are fast and prevent presentation differences from reaching a more costly review.
- Static analysis: look for incompatibilities and errors that can be detected without running all application flows. Adjust the rules to the project's actual code and configuration.
- Tests: run unit tests first, then add integration or end-to-end tests according to the risks they cover and the services they need.
- Artifact validation: check that the generated package or image contains what is needed to run and excludes development files, local data, and secrets.
Not all applications need the same tests or the same order. If static analysis takes much longer than a small unit test, it may make sense to run both checks in parallel after installing dependencies. Independent tasks can also run in parallel to reduce wait time, provided they share a reproducible baseline and their results are associated with the same change.
However, avoid blindly parallelizing steps that modify the same directory or depend on previous results. Separate common setup from subsequent tasks, limit concurrency for shared services, and make dependencies between stages clear. The goal is to shorten feedback time without making the pipeline unpredictable.
Decide what blocks and what runs later
As a starting rule, block integration when a check relevant to the change's safety fails: installation, agreed analysis, required tests, or package validation. An informational task—for example, a check still under evaluation—can report results without blocking for a defined period. It should have an owner, a review date, and criteria for becoming mandatory; otherwise, warnings become permanent and lose their value.
Fast checks should provide early feedback on every change. Expensive tests can run in parallel, in a later stage, or at a different frequency if time or infrastructure makes that appropriate. However, reserving all significant validation for after integration leaves a window during which changes have not been checked. Define what is required before integration and what remains as additional validation, taking into account the impact of a late failure.
A successful run is not the same as an approved deployment. CI verifies the change and may generate an artifact; the delivery process decides how to promote it, to which environment, and under what controls. Keeping this boundary explicit prevents a validation task from accidentally publishing to production. If automatic deployment is used, define its conditions, approvals, rollout strategy, and rollback mechanism separately.
Protect configuration and secrets
Secrets must not be added to the repository, example configuration files, or run reports. Use the CI environment's secret management mechanism, limit availability to the tasks that need them, and avoid granting production credentials to validations that only require isolated services.
Review logs as well: an exception, a failing test, or a diagnostic command can print sensitive variables. Masking values helps, but does not replace avoiding writing them in the first place. Use test data that does not expose real information, and define a procedure for revoking credentials if they appear in a log or artifact.
Make failures diagnosable
A red status without context forces people to repeat work and turns CI into a black box. Keep test and analysis reports, the output needed to identify the failed step, and identifiers for dependency or artifact versions. Avoid logging personal data, secrets, or indiscriminate dumps of the environment.
When a test fails intermittently, do not mark it as successful after unlimited retries. Record which tests are flaky, how often and under what conditions; investigate causes such as concurrency, external dependencies, shared state, or time limits. If an unstable test is temporarily isolated, document the risk, assign an owner, and set a date for restoring its blocking status.
It is also useful to distinguish a code failure from an infrastructure problem. Report when services could not be started, dependencies could not be obtained, or a task could not be completed because of insufficient resources. A retry may be reasonable after a transient interruption, but it should be limited and visible; hiding the first failure makes recurring problems harder to detect.
Adapt CI to a legacy application
In an older system, turning on strict rules all at once can block useful changes and encourage uncontrolled exceptions. Start with a baseline: identify which tests pass today, what pre-existing errors the analysis reports, and how long each stage takes. Do not present an existing problem as a regression, but do not let the baseline become an indefinite excuse either.
- First make stable, reproducible checks mandatory, such as installation and a reliable test suite.
- Record existing findings and require that new changes do not expand the problem, if the tool and project support that comparison.
- Add tests around the areas with the greatest change risk and gradually expand their coverage.
- Reduce exceptions through small, reviewable changes; assign an owner and a date to each temporary exception.
- Measure execution time and failure causes to optimize specific stages, rather than removing validations without knowing which risks they covered.
Good continuous integration in PHP is not defined by the number of stages, but by repeatable, understandable results. If the team can explain what each step validates, what blocks integration, and how to investigate a failure, the pipeline helps them make evidence-based decisions about when a change is ready to move forward.