A PHP deployment strategy with rollback is not about keeping a button to return to the previous version. It is an operational design that makes it possible to withdraw code without leaving incompatible data, duplicate asynchronous jobs, or in-progress processes running rules that have already been discarded. Rollback must be an option prepared before release, not an improvised reaction during an incident.
Small deployments reduce the blast radius: they introduce fewer variables, make it easier to identify the change that caused the issue, and shorten recovery. However, a small change can affect payments, authentication, permissions, inventory, or communications. Therefore, change size does not replace technical controls or explicit criteria for stopping a release.
Rollback is designed before an incident exists
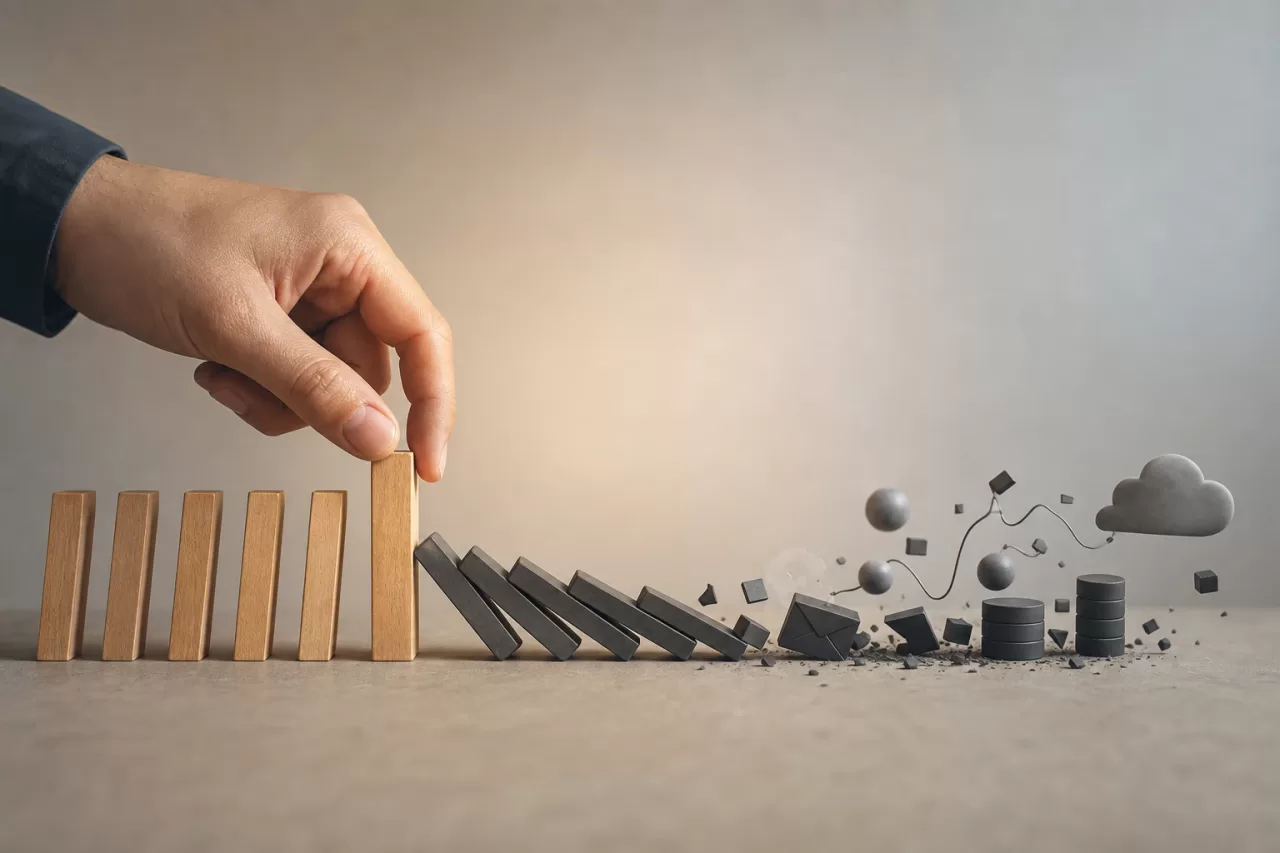
Reverting code is simple only when the change has not altered shared state. In production, a version may have written data, sent messages to a queue, activated a scheduled task, or called an external service. Returning to an earlier commit without reviewing those effects can hide the initial error and create one that is harder to diagnose.
Before approving a deployment, the team must be able to answer four questions:
- Which artifact will be released: an identifiable version, built once and available for restoration.
- Which state changes: database schema, cache, files, search indexes, queues, external providers, and configuration.
- Which version can read and write that state: new code, previous code, or both during a temporary window.
- Which signal requires action: error threshold, critical-path failure, queue delay, latency degradation, or confirmed functional impact.
The rollback unit must be defined. It can be the entire application, a service, a queue consumer, or functionality enabled through configuration. It is important not to confuse deployment, which installs software, with release, which makes behavior available. Separating them makes it possible to deploy inactive code and expose it later after validating technical conditions.
Classify changes by their rollback capability
Not all changes allow the same treatment. A presentation adjustment or an internal fix without state changes is usually reversible by restoring the previous artifact. By contrast, a destructive migration, an API contract change, or a new business rule that has already produced external effects requires an additional strategy.
Normally reversible changes
- Logic fixes that preserve input and output contracts.
- Template changes, provided they do not depend on removed fields.
- New routes or endpoints that do not modify existing resources.
- Internal optimizations without schema or semantic changes.
Changes that require temporary compatibility
- Renaming or replacement of columns, JSON fields, and events.
- Format changes in queue messages or webhooks.
- New validation constraints on existing data.
- Changes to authentication, permissions, or calculation rules.
- Integrations that create charges, orders, notifications, or changes in external systems.
For shared data, the safest pattern is usually expand, migrate, contract. First, a compatible structure is added; then, the code temporarily supports both the old and new formats; the necessary data is migrated or backfilled; and only after the old version has been permanently removed is the obsolete part deleted. For example, adding a nullable column and writing to both fields during a transition is recoverable; directly renaming or deleting a column used by the previous version is not.
Migrations must be treated as deliverables independent from code. A forward-only migration can be correct, but the plan must then state that an application rollback does not imply reverting the schema. Avoid an automatic down migration if it could delete data generated after the change or if its result depends on the actual production state.
Prepare artifacts, configuration, and prerequisites
The same artifact must progress across environments. Building dependencies or modifying code directly on each server makes it impossible to know which version is running and makes restoring a known version more difficult. In a PHP application, the artifact can include versioned code and resolved dependencies; sensitive, environment-specific configuration must be injected through external mechanisms, not embedded in the package.
At a minimum, record the version identifier, release date, relevant functional configuration, and the person responsible for the decision. This speeds up both investigation and returning to a specific version.
Before deployment, verify in an automated and visible manner:
- Unit, integration, and contract tests proportionate to the change.
- Dependency resolution and compatibility with the required PHP version, extensions, and services.
- Migration status, data expansion plan, and estimated execution time.
- Dependency health: database, cache, storage, internal APIs, and critical providers.
- Capacity and behavior of workers, queues, and scheduled tasks.
- Availability of the previous artifact and a tested procedure to restore it.
Checks must not be limited to whether the PHP process responds. A health endpoint may confirm that PHP-FPM is active and still fail to detect an authorization error, a slow query, or a blocked consumer. Define small synthetic paths that represent critical operations without executing irreversible actions.
Release gradually with clear owners and limits
Gradual exposure reduces the scope of a failure, but it works only if traffic or instances can be truly separated. A fraction of instances can be updated, a capability can be enabled for a controlled segment, or part of the requests can be directed to the new version. The choice depends on the architecture and the type of shared state.
Assign explicit roles during the release window:
- One person executes and records the steps.
- Another observes relevant metrics, logs, and traces.
- An owner has the authority to stop or roll back without waiting for ambiguous approvals.
- The business or support team is aware of the expected effects if the change affects a sensitive operation.
Also establish an observation window. It is not enough to release, see a correct HTTP response, and move on to the next change. Some defects appear when a queue is processed, a cache expires, a scheduled task runs, or a user completes a longer flow.
Verify afterward: service, data, and business effects
Post-release verification must combine technical and functional signals. General metrics are useful, but a stable latency average can hide the failure of a minor yet critical operation.
- Critical paths: authentication, primary reads and writes, payments, order creation, or actions involving permissions.
- Errors: PHP exceptions, 5xx responses, unexpected 4xx increases, validation errors, and dependency failures.
- Performance: latency by endpoint, worker saturation, database connections, and resource consumption.
- Asynchronous processing: queue size and age, retries, failed messages, and idempotency.
- Business effects: incomplete transactions, duplicates, invalid state changes, or drops in conversions that the team can verify.
Decision criteria must be verifiable. Continue if the defined paths work, there is no sustained increase in errors, and queues remain within their acceptable delay. Stop expansion if an anomaly appears that still requires diagnosis. Roll back if the previous artifact is compatible with the current state and restoration clearly reduces the impact. Fix forward if reverting would break compatibility, would not undo external effects, or would take longer than applying an isolated, validated fix.
Manage queues and processes started by a withdrawn version
Workers are a common source of incomplete rollbacks. Web code can be withdrawn while messages created by the new version or long-running processes that continue to run old logic remain. The plan must indicate how to drain, pause, restart, or isolate consumers without losing traceability.
Consider a hypothetical flow: a PHP application publishes a message to confirm an order. The new version adds a field to the message and changes the order status before sending it. If it must be withdrawn, the previous consumer must safely ignore the additional field, or the message must carry a version that allows it to be routed to a compatible consumer. In addition, confirmation must use an idempotency key so that a retry does not produce two external actions.
{
  "event": "order.confirmation_requested",
  "schema_version": 2,
  "idempotency_key": "unique-operation",
  "order_id": "identifier"
}
Before rolling back, pause the intake of new jobs if necessary, identify messages in transit, and confirm which consumers can process them. Then review failures and retries in a controlled manner. Do not delete a queue to recover speed: doing so may remove necessary evidence or leave business operations half completed.
Turn the plan into a repeatable practice
A mature strategy does not depend on individual memory. Maintain a brief runbook for each service with approved commands, log locations, observability dashboards, owners, stopping conditions, and known rollback limits. Rehearse the procedure in a representative environment, especially after infrastructure, queue, migration, or integration changes.
After every incident or rollback, review whether detection, compatibility, automation, or the decision failed. The goal is not to avoid every rollback; it is to be able to choose between reverting and fixing forward with sufficient information, without turning a localized incident into data loss or a larger outage.