The decision between MySQL and PostgreSQL should not start with which one someone on the team knows best or with an impressive query seen in a demonstration. It must start with the operations the application will need to support reliably: recording orders, reserving availability, recalculating balances, accepting simultaneous changes, generating reports, or integrating external data.
Both engines are mature options for a transactional PHP application. The relevant difference emerges when the data model, behavior under concurrency, integrity guarantees, and operational load the organization can take on are specified. Choosing well does not eliminate design work; it reduces incompatibilities between business rules and the data platform.
The starting point is critical operations
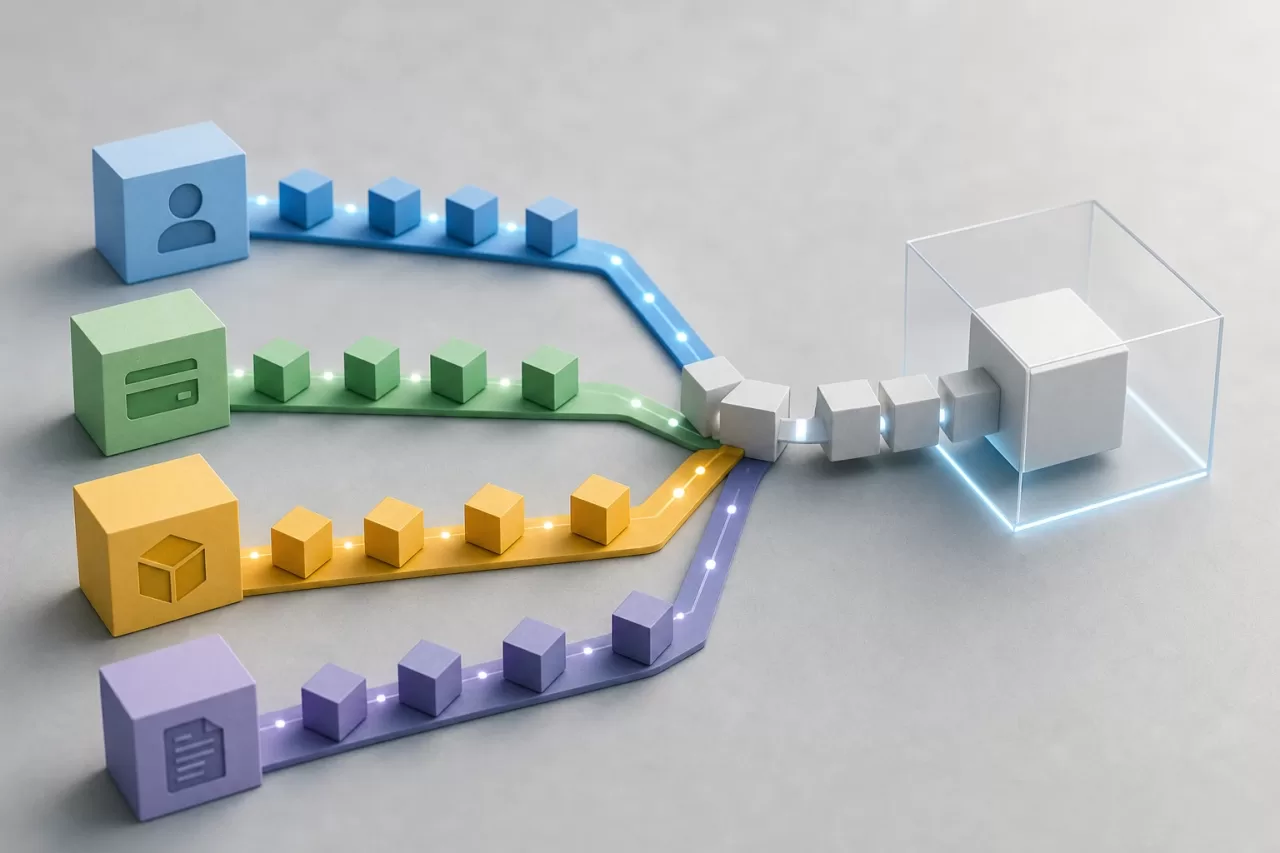
Before comparing features, describe the flows that cannot lose data, duplicate effects, or leave inconsistent states. User registration differs from confirming a payment, reserving an inventory unit, or consolidating an invoice. Each operation has requirements for atomicity, ordering, latency, and traceability.
Turn use cases into a verifiable list. For each one, note which data it reads, which records it writes, which rule must be met, how many users or processes can run it at once, and what happens if it is interrupted. This inventory prevents decisions based on a technology preference when the real problem is a poorly defined state model.
- Business operations: registrations, cancellations, state changes, charges, refunds, and reservations.
- Asynchronous processes: imports, retries, queues, recalculations, and notifications.
- Operational reads: filtered lists, detail views, permissions, and frequent searches.
- Analytical reads: aggregations, time comparisons, exports, and reports.
- Integrations: APIs, webhooks, accounting systems, and external data sources.
When considering how to choose MySQL or PostgreSQL for a PHP application, the useful question is: which errors must the system prevent even if the application has a failure, two requests are simultaneous, or a process is retried?
Inventory of data, rules, and uncertainties
Model entities, relationships, and lifecycles before selecting the engine. Identify primary keys, required relationships, uniqueness, amounts, dates, states, and semi-structured documents. Also separate operational data from data that is only used for auditing, search, or analysis.
Database constraints are a second line of defense, not a substitute for PHP validations. The application must provide understandable messages and validate input; the database must enforce invariants that cannot be violated. For example, a foreign key can prevent nonexistent references, a uniqueness constraint can prevent duplicating an external identifier, and a CHECK constraint can restrict permitted values.
PostgreSQL is often especially convenient when the domain needs rich types, expressive checks, complex analytical queries, or a deliberate combination of relational structure and JSON documents. MySQL is also a solid choice for many business products with relational schemas, transactions, and conventional query patterns. The decision should not turn these trends into absolute rules: validate the actual queries and rules.
Flexible data without losing the contract
Storing variable attributes in JSON can speed up an initial integration, but it does not eliminate the need to define which fields exist, how they are validated, and how they are queried. If an attribute is involved in permissions, pricing, availability, or recurring reports, it normally deserves an explicit structure and appropriate indexes. Semi-structured documents are better suited to variable data with a known contract than to hiding a model that nobody has decided on.
Evaluate writes, transactions, and concurrency
Concurrent writing is where many architectural decisions become apparent. It is not enough to know that both engines support transactions: you must test which rows are updated, how long each transaction lasts, which indexes are involved, and how conflicts are managed.
An inventory reservation, for example, must prevent two requests from confirming the last unit. Depending on the flow, the solution may require a conditional update, deliberate locking, or optimistic version control. It is not advisable to open a transaction, call a remote service, and hold locks while waiting for the response. Limit the transaction to the necessary data operations and design compensations or retries for external failures.
- Measure simultaneous registrations on the same entities or scarce resources.
- Define which operations can be retried without duplicating effects through idempotency keys.
- Review execution plans and indexes for updates, not only for listings.
- Record wait times, locks, transaction errors, and slow queries.
- Test with representative volumes and concurrency, not only with an empty database.
In PHP, use a data access layer that makes transaction boundaries explicit. PDO, an ORM, or a query builder can make the work easier, but they do not decide isolation, update ordering, or the retry strategy on their own. A migration must also reflect associated constraints, indexes, and data changes, rather than merely creating columns.
Distinguish operational reads from reports
An operational screen usually needs predictable responses with specific filters, sorting, and pagination. A report may span extensive periods, join many entities, and calculate aggregates. Mixing both patterns without design causes a heavy export to compete with daily activity.
Start with the queries that will run frequently and those that can degrade the service. Define filters, expected cardinality, ordering, pagination, and consistency requirements. Create indexes for observable patterns, checking that they do not penalize writes unacceptably. An index is not an abstract improvement: it consumes space, adds work when inserting and updating, and must justify a specific query.
PostgreSQL offers a broad set of tools for complex queries, aggregations, window functions, and extensibility. MySQL can effectively solve many well-indexed relational queries and is a reasonable option when patterns are clear. If the main need is advanced text search, large-scale analysis, or reporting at scale, also evaluate specialized components. Do not force the transactional database to take on a different role without defining synchronization, consistency, and recovery from delays.
Operations: the criterion that must not be left until the end
The best technical choice fails if it cannot be restored, updated, or diagnosed. Document who will administer the engine, how patches will be applied, which environment reproduces incidents, and which procedure allows a service to be recovered after human error, a failed migration, or infrastructure loss.
Backups are not sufficient if restores are never tested. Establish recovery objectives aligned with the product's impact and periodically verify that a backup can rebuild the database, apply the necessary logs if they exist, and start the application with consistent data. Protect backups and credentials, restrict privileges, encrypt communications where appropriate, and maintain an audit trail of administrative access.
Monitoring must connect technical symptoms with impact: connection saturation, storage growth, slow queries, locks, replication lag, authentication errors, and maintenance task duration. The team must know how to interpret these signals and have clear procedures. A technology that nobody can operate confidently has a greater hidden cost than a marginal performance difference.
Alternatives that increase risk
Choosing an engine because of a single query, a future scale expectation without evidence, or because another company uses it usually postpones the real decision. It is also risky to install MySQL and PostgreSQL in the same product without a boundary of responsibility. Two engines mean two chains of backups, updates, alerts, permissions, migrations, and operational knowledge.
Use both only if there is a defined and sustainable reason: for example, a legacy platform that must temporarily coexist with a new service, or a separate data responsibility with clear interfaces. Define ownership of each piece of data, the source of truth, synchronization, failure handling, and the retirement plan. Replicating data between engines without these rules introduces divergences that are difficult to explain.
Practical matrix for making and reviewing the decision
Score each option using evidence from the current system and near-term risks, not preferences. Assign greater weight to flows whose corruption or unavailability would have significant consequences. The score does not replace technical review, but it forces assumptions to be made visible.
- List five to ten critical operations and their level of concurrency.
- Assess the complexity of queries, reports, data types, and search needs.
- Identify the integrity rules that must be enforced outside the application.
- Evaluate actual capabilities for operations, restoration, monitoring, and internal support.
- Build a brief test with representative queries, data, and conflicts.
- Estimate the cost of a later change: migration, downtime, validation, and training.
- Document the decision, the accepted limits, and the signals that would require reviewing it.
The right choice is the one that makes it possible to maintain critical operations with clear rules, verifiable performance, and operations the team can sustain.
MySQL or PostgreSQL are not an architectural identity. They are components that must fit the business model, PHP code, delivery practices, and operational responsibility. Deciding based on specific flows makes it possible to start with a reasoned foundation and retain objective criteria for evolving it.