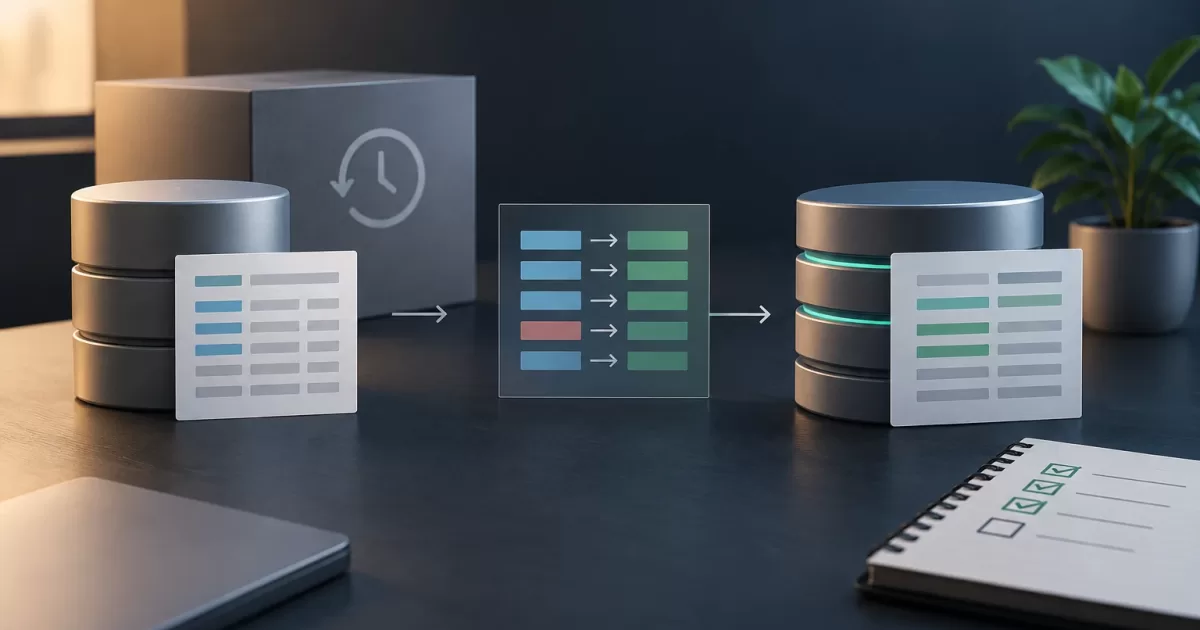
A backup makes it possible to recover data, but restoring it directly over the live database can erase legitimate changes made after the backup was taken. When the problem affects a single record or a limited set, the goal is usually to recover the lost information while preserving the rest of the current state. This means treating recovery as a process of comparison and reconciliation, not as a simple replacement.
The right strategy depends on the database engine, the schema, the availability of audit logs, and the extent of the damage. In a PHP application, it is advisable to separate recovery logic from the application in production, document decisions, and test validations before writing data. If you cannot determine which changes are safe, stopping and preparing a manual reconciliation is usually less risky than automating an overwrite.
Define what data recovery means
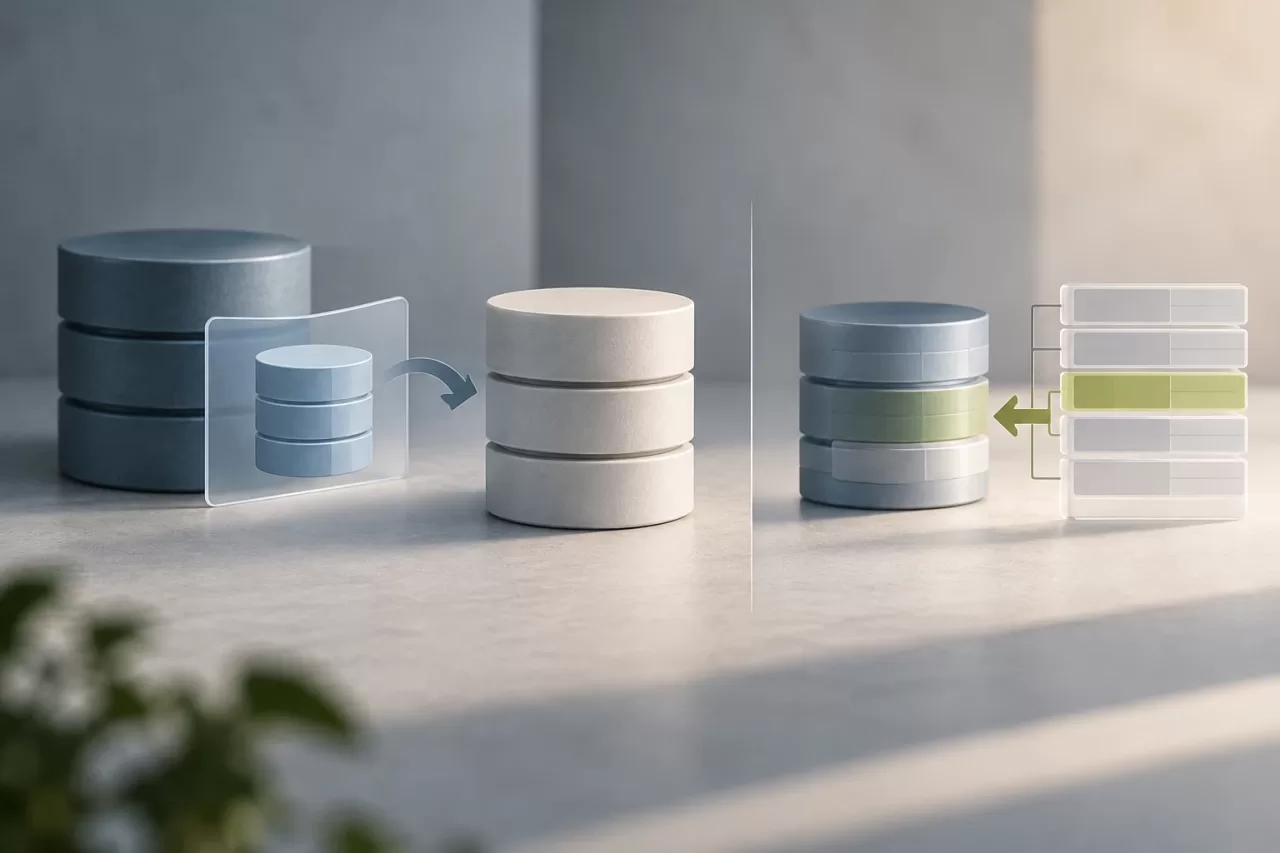
A full restore replaces a database, schema, or broad set of data with the contents of a recovery point. Selective recovery, by contrast, attempts to restore specific rows or values without changing the other active data. Before choosing an approach, describe the expected outcome precisely: which entity is missing or was altered, which fields need to be recovered, and which later changes must be preserved.
Define the scope using stable identifiers, such as the primary key, rather than values that may have changed, such as a name or email address. Also clarify whether the incident affects related records: for example, an order may depend on line items, payments, addresses, and status events. Recovering only the main row can leave an entity inconsistent; recovering the entire group can include valid changes that should not be rolled back.
- Record the symptom, approximate time period, and who reported the problem.
- Identify the relevant tables, primary keys, foreign keys, and constraints.
- Specify which fields should return to an earlier value and which should remain as they are.
- Determine who will approve the operation and which checks will establish that it is complete.
Choose a recovery point and reconstruct the context
Select a recovery point that allows you to reconstruct the required state, not necessarily a backup from before the damage occurred. Depending on the incident, you may need to compare multiple backups, transaction logs, and audit data to identify what information should be recovered and which later context should be preserved. Point-in-time recovery can produce a temporary database that is useful for extracting data, but that does not mean its entire contents can safely be transferred to production.
Confirm the date and time zone, backup coverage, the schema it was created with, and the results of any available integrity checks. An unverified backup should not be treated as a reliable source by default. Also check whether identifiers may have been reused or whether processes are writing to the affected tables during the investigation.
Restore the backup to an isolated instance with restricted access and no write connections to production. The application should not accidentally point to this instance or run scheduled jobs against it. If the data contains personal or sensitive information, limit access and apply the safeguards intended for that data. The isolated environment allows you to compare states without adding risk to the live database.
Compare without assuming the backup reflects the current truth
Compare candidate rows in the backup with the current rows using their stable keys. For each one, distinguish among three situations: the record no longer exists, it exists but has modified fields, or there are no relevant differences. If update timestamps, event history, or audit data are available, use them to understand when and why it changed. A timestamp alone does not prove which user made the change or whether it should be preserved.
Selective recovery requires one essential precaution: do not automatically copy an entire old row when some of its fields have changed legitimately. For example, a comparison may show that a record lost a descriptive field, while its status, owner, or relationship to another entity changed later. Restoring only the missing field may be safer than replacing the entire row, provided the business rules allow it.
Also review uniqueness conflicts, foreign keys, required columns, default values, and rules enforced by the application. In systems that use soft deletes, check whether the record is marked as deleted rather than absent. Tables involved in the same business operation may need to be reconciled together to avoid inconsistent balances, statuses, or references.
Apply a bounded and verifiable operation
Prepare a plan that specifies the exact set of keys and columns to be modified. Before executing it, preserve a copy of the current state of those rows or an equivalent rollback mechanism. Test the plan against a recent copy of the live database and compare the result with what you expect. The test should include the actual constraints and dependencies, not just an import of isolated rows.
When the database engine and operation allow it, perform the changes in a transaction. A transaction does not replace review: some restore or import actions may behave in engine-specific ways, and external processes may update data concurrently. Use conditions that detect unexpected changes between comparison and writing. If a row no longer matches the reviewed state, stop the operation and analyze it again instead of silently overwriting it.
In a PHP application, a controlled task or maintenance command can validate inputs, limit the affected keys, and log results. Avoid building SQL statements by concatenating values. Use parameterized queries and the transaction mechanism provided by the application's data access layer. Keep the operation out of public routes, and do not expose credentials or backups in plain-text logs.
Before committing the changes, verify the number of affected rows, constraints, and relevant relationships. Then check the recovered values and the application's behavior in related business operations. If a validation fails before a transaction is committed, roll back the transaction. If it has already been committed or there are irreversible effects, do not improvise another write: activate the approved rollback or recovery plan before executing, following the tested procedure to restore the accepted state and verify it. If the plan cannot recover a consistent state, stop further modifications, preserve evidence, and escalate the decision to the responsible people.
Document the decision and know when not to automate
Document the incident, the recovery point used, the keys examined, the fields restored, and the later changes preserved. Record who reviewed and approved the operation, when it was run, which validations were performed, and the outcome. Do not include unnecessary sensitive data in the log. This traceability makes it possible to explain the decision and supports a later investigation.
Choose manual reconciliation if reliable keys are unavailable, business operations conflict, you cannot distinguish an accidental change from a legitimate one, or recovery affects relationships whose meaning depends on context. A full restore may be appropriate in the event of extensive corruption, but it requires assessing its impact, downtime, loss of later changes, and recovery procedure. It should not be chosen simply because it is easier to execute.
- Selective recovery: the damage is clearly defined, the keys are reliable, and the differences can be verified.
- Manual reconciliation: there are concurrent changes or business rules that require human judgment.
- Full restore: the damage is extensive and there is an approved plan to manage downtime and the changes that would be lost.
Checklist before closing out the recovery
- Preparation: Have the scope, keys, dependencies, and expected outcome been identified? Has an appropriate recovery point been selected and verified?
- Environment and approval: Has the backup been restored in isolation, access been restricted, and the procedure been tested? Have the responsible people approved the operation and the rollback or recovery plan?
- Execution: Has the current state of affected rows been preserved, writing been limited to the intended keys and fields, and concurrent changes been detected?
- Verification: Have affected rows, constraints, references, and business behavior been reviewed? If a check fails, have further writes been stopped and the approved procedure activated?
- Traceability: Have the decision, execution, validations, preserved changes, and outcome been recorded without including unnecessary sensitive data?
If you cannot answer yes to the applicable items, postpone writing to production. The decision between selective recovery, manual reconciliation, and a full restore should be based on the extent of the damage, the reliability of the evidence, the operational impact, and the actual possibility of recovering a consistent state.